
Architecting Fabric Data Agents for Weekly Forecasting: A Governance-First Guide
How to architect a Microsoft Fabric data agent for weekly forecasting: separate the forecasting engine from the agent, pin the weekly data contract, store revisions for point-in-time comparison, and validate answers before publication.
Introduction
A Fabric data agent is a conversational query layer, not a forecasting engine. Microsoft's documentation is explicit on this point: the agent "doesn't perform advanced analytics, machine learning, or causal inference. It simply retrieves and processes structured data based on the user's query" (create a Fabric data agent). If you are responsible for a weekly forecast process and you are putting a data agent in front of it, that sentence defines your architecture problem. The agent will answer questions about next week's number. It must not be the thing that produces that number.
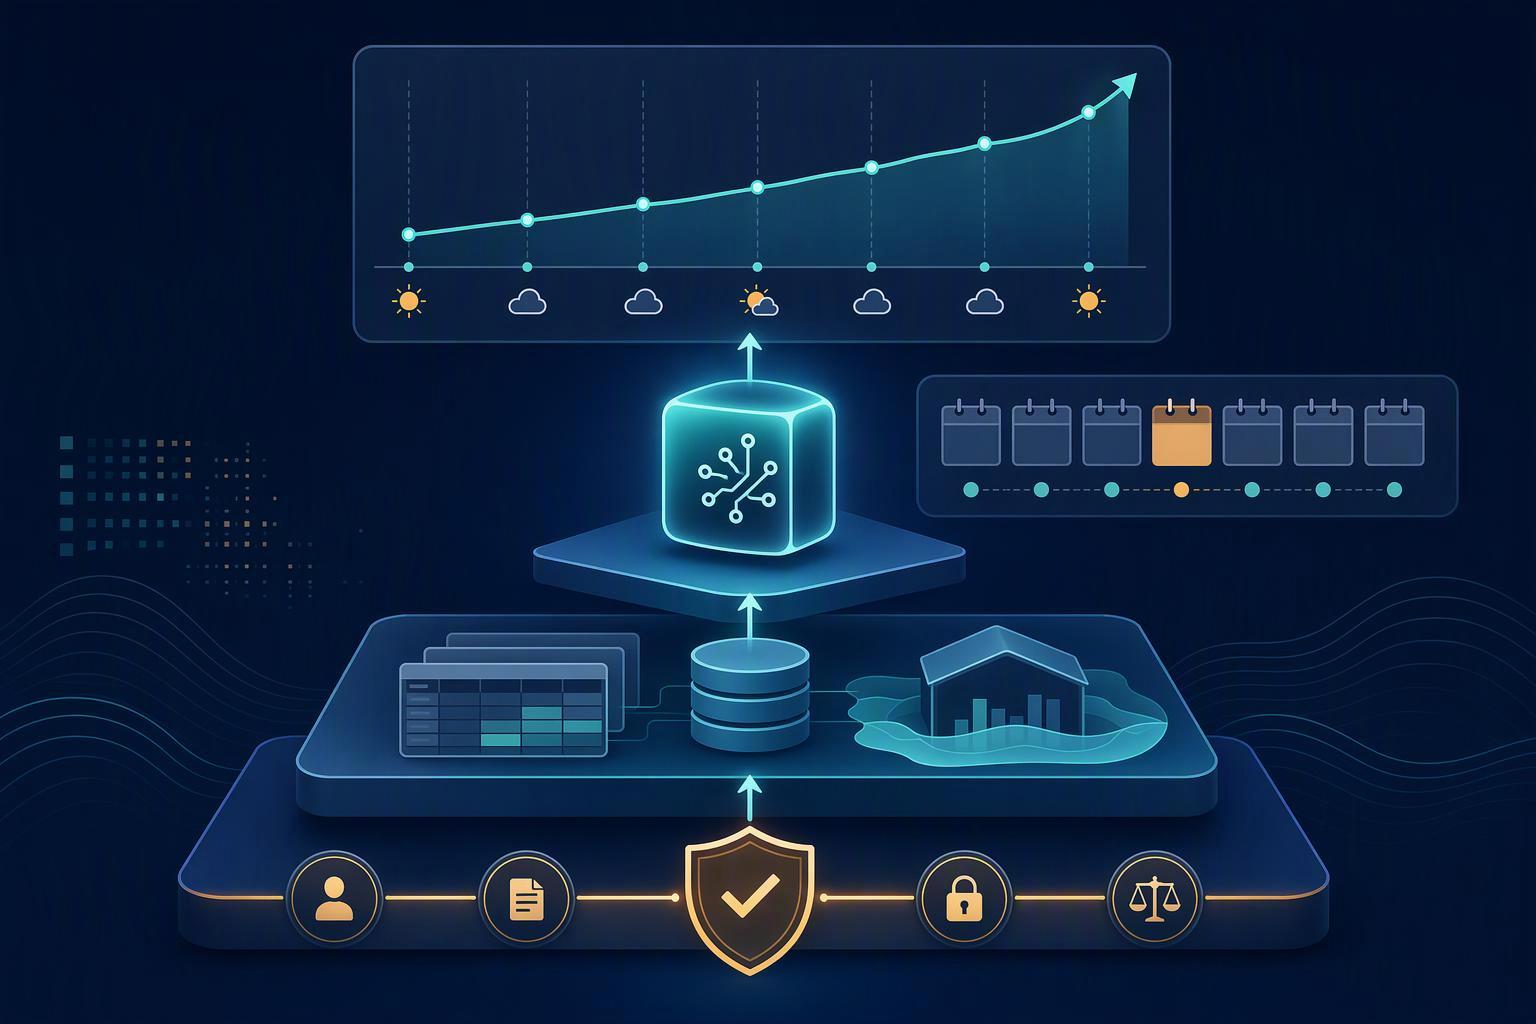
The work therefore splits in two. A deterministic pipeline computes the forecast and writes it to a governed table. The agent reads that table and nothing else. Everything that makes the resulting answers trustworthy sits in the seam between them: a data contract that fixes grain and calendar, storage that preserves revisions, instructions and example queries that can be tested, an evaluation set that runs before publication, and a review record that says who approved which number and when. Prompt tuning does not substitute for any of these.
This guide is written for a data architect or analytics lead who already runs, or plans to run, a Fabric data agent against a weekly forecast process. It proceeds in the order the controls have to be built: engine separation, the weekly contract, revision storage, testable instructions, evaluation, approval governance, failure modes, and an acceptance checklist. The platform behavior cited throughout comes from Microsoft Fabric documentation; the calendar rules come from ISO 8601 and the DAX reference; the case for keeping data vintages comes from forecast-evaluation literature. None of it assumes a particular deployment.
Separate the Forecasting Engine from the Agent Layer
The first design decision is a boundary: the agent retrieves forecast values, it never derives them. That boundary is not a stylistic preference. It follows from how the agent works. For SQL sources, the agent uses a built-in NL2SQL service that translates the question into T-SQL using the selected schema, instructions, and example queries, validates the generated query against the schema selection so it only references approved tables and views, and executes it through the SQL Analytics Endpoint (add and configure data sources). A query that aggregates historical demand and calls the result a forecast is a perfectly valid T-SQL statement. The agent has no mechanism to know it is wrong.
So build two layers.
Upstream: the forecasting engine. A notebook, a low-code AutoML run, or an external model produces point forecasts on a schedule. Fabric's low-code AutoML interface lists forecasting as a supported task for predictions over time-series data (low-code AutoML), and notebooks can handle batch scoring with open-source libraries or the Spark PREDICT function (Data Science in Fabric). Whichever you use, its only output contract is the forecast table.
Downstream: the agent. The Fabric data agent is configured over the forecast table plus the dimension tables needed to filter and label it (product, region, channel, calendar). It is a read-only conversational surface on top of that schema.
The forecast table needs explicit metadata columns, because the agent's answers are only as interpretable as the columns it can select. The following is a proposed pattern, not a product requirement:
Column | Purpose |
|---|---|
| Identifies the pipeline run that produced the row |
| The forecasted series (product × region × channel, or your grain) |
| The first day of the forecast week, in the pinned convention |
| The point forecast |
| Which model or pipeline version produced it |
| When the run executed, in UTC |
|
|
Four controls keep the boundary intact. First, scope schema selection to the forecast table and its dimensions; the agent validates generated queries against that selection, so an out-of-scope table is refused rather than silently queried. Second, grant read-only access to the underlying source. Third, write data source instructions that forbid recomputation in plain terms — the forecast table is the only source of forecast values, and history tables are for actuals only. Fourth, make every example query read from the forecast table, so the retrieved few-shot patterns never demonstrate an aggregation of history as a forecast.
One capacity note: data agents require a paid F2 or higher Fabric capacity or Power BI Premium per capacity (P1 or higher), and AI experiences such as data agents are not supported on trial capacities (Fabric trial). Confirm the capacity before designing around the agent.
Define the Weekly Data Contract Before the Agent Answers
Most wrong weekly answers are grain or calendar errors, not retrieval errors. The agent will faithfully execute a query that sums two grains together or labels a Sunday-start week as ISO week 1. Pin the contract before the agent is configured.
Grain. One row per series per forecast week. State it in the data source instructions and enforce it with a uniqueness test on (series_key, week_start, forecast_run_id) in the pipeline. If the table can hold both weekly and daily rows, or series keys at different hierarchy levels, the agent has no way to know which rows to sum.
Week convention. ISO 8601 weeks start on Monday and end on Sunday, and each week's year is the Gregorian year in which the Thursday falls, so week numbering near 1 January can differ from the calendar year (ISO week date). DAX is not ISO by default: WEEKNUM uses System 1, where the week containing 1 January is week 1, and only return_type 21 selects the ISO 8601 System 2 definition (WEEKNUM). A semantic model and a SQL table can therefore disagree about which rows constitute "week 1" without either being broken. Pin one convention in the data source instructions and use it in both places.
Fiscal calendar. If the business reports on a 4-4-5 or 13-week fiscal calendar, define it once — in data source instructions, since those are sent to the query-generation tool every time the source is used (topics) — and reference the same definition in any semantic model. Two definitions in two places produce two answers to one question.
Timezone cutoff. State the reporting timezone and the exact instant at which a week closes. Store as_of_utc on every row so the agent can disclose when the number was produced. Without a cutoff, a late-arriving record changes last week's answer retroactively and nobody can tell whether the agent is wrong or the data moved.
Blank versus zero. A missing forecast is not a forecast of zero, and SQL aggregation will not preserve that distinction for you. Require an explicit status value (pending, approved, suppressed) and instruct the agent to treat NULL as "no forecast." A suppressed series and a zero forecast are different business facts; the schema should say so.
Contract assertions a data test can enforce:
Exactly one row per (
series_key,week_start,forecast_run_id).week_startalways falls on the pinned first day of the week.as_of_utcis non-null and not in the future.statusis restricted to the allowed set; no NULLs.Every
series_keyin the forecast table exists in the dimension table.No row has
forecast_valuepopulated whenstatus = 'suppressed'.
Store Forecast Revisions for Point-in-Time Comparison
The moment a forecast is revised, week-over-week comparison becomes a question about which version of the number you are comparing. Two time dimensions are in play: valid time (the week being forecast) and transaction time (when the forecast was produced or revised). SQL:2011 formalized these as application-time period tables, system-versioned tables, and bitemporal tables (temporal database). You do not need SQL:2011 syntax to get the benefit; you need the two dimensions represented in the data.
Make the forecast table append-only. Each pipeline run writes new rows keyed by forecast_run_id, with as_of_utc and a revision_reason where a revision supersedes a prior approved value. Never update a forecast value in place. Then expose a view that resolves "latest approved revision as of timestamp T" for each series and week, and point the agent at the view rather than the raw history. The agent's SQL stays simple; the point-in-time logic lives in one place that you can test.
This matters most for the comparison people actually ask for: how did this week's forecast for week 42 change against last week's forecast for week 42? Joining on week_start alone compares the latest revision to the latest revision and returns zero change. The correct query filters each side to its own as_of_utc — the run from this Monday and the run from last Monday — and compares them.
The forecast-evaluation literature makes the same point about actuals. Croushore's discussion of real-time data vintages asks which vintage of the data should serve as the "actual" when evaluating a forecast, and notes that the forecast evaluation literature has used many different concepts (Forecasting with Real-Time Data Vintages). The choice changes the evaluation result. If you overwrite actuals and forecasts, you lose the ability to reconstruct what the business knew at the time a decision was made. Store vintages; resolve them in views.
The pattern assumes the pipeline can write a new run rather than mutate rows, and that the view is the only object the agent is permitted to query for forecast values. Both are design choices you control.
Write Agent Instructions and Example Queries That Can Be Tested
The agent's configuration surfaces are where governance becomes executable, but only if each instruction maps to a behavior you can test. Four surfaces matter for a forecast agent.
Agent instructions accept up to 15,000 characters of plain English and guide the agent on routing and on organizational terminology (create a Fabric data agent). Data source instructions are sent to the query-generation tool every time that source is used, so they carry rules that must apply to every question. Example queries are natural-language/SQL pairs; the agent retrieves the top three most relevant by vector similarity when the source is used (data agent configurations). Topics (preview, SQL sources, preview runtime) hold up to 1 million characters of subject-organized guidance that the agent searches and passes to NL2SQL only when relevant (topics).
Write instructions that state, in plain terms:
The forecast view is the only source of forecast values. Never derive a forecast by extrapolating, averaging, or trending historical actuals.
Filter to
status = 'approved'unless the user explicitly asks for pending or suppressed values.Always state the
as_of_utctimestamp in the answer.Use the pinned week convention and name it in the answer (for example, "ISO week 43 of 2026").
Treat NULL as "no forecast," never as zero.
If a question could mean actuals, plan, or statistical forecast, ask which one before querying.
Then write example queries that each encode one testable behavior: latest approved forecast for a named series; week-over-week delta between two as_of_utc timestamps; a series with a known gap, so the expected answer is "no forecast"; and a deliberately ambiguous "what's the forecast for Q4?" paired with the clarifying question the agent should ask. Because the agent retrieves only the top three examples per question, keep the library focused on forecast patterns rather than accumulating generic SQL.
Two documented constraints shape how users should be told to work with the agent. Responses are capped at 25 rows and 25 columns, and previous chat history can influence later answers — Microsoft's own example is that "show all rows for this year" still returns at most 25 rows, and follow-ups are answered from that limited context, so starting a new chat session is recommended (concept). Put that in the instructions: for a full weekly pull, use the pipeline output or a report; use the agent for conversational checks. The agent also does not currently support non-English input, so keep instructions and examples in English.
Finally, publish deliberately. A published agent keeps serving its published version while you refine the draft, and you can test the same queries against both (sharing and permissions). Use that to stage instruction changes rather than editing the version your users depend on.
Evaluate the Agent Before Trusting Its Weekly Output
Evaluation is the step that turns the configuration into evidence. The Fabric SDK evaluation feature (preview) lets you define ground-truth question/answer pairs in a pandas DataFrame, call evaluate_data_agent, and inspect summary and step-level results; it writes a summary table and a _steps table with detailed reasoning and execution (evaluate your data agent).
Build the test set from the data contract rather than from imagination. One question per rule:
Grain: "What is the approved forecast for series X in week 43?" — expected answer computed with the same SQL the pipeline uses.
Calendar edges: a question spanning the year boundary where ISO week-year and Gregorian year diverge, and a question about fiscal week 1.
Blank versus zero: a series with a known gap — expected answer is "no forecast," not 0.
As-of comparison: the same week's forecast at two different
as_of_utcvalues.Ambiguity: "What's the forecast for next quarter?" — expected behavior is a clarifying question, not a guess.
Scope: a question about a table outside the selected schema — expected behavior is a refusal or redirect.
The SDK uses a built-in prompt to judge whether the actual answer matches the expected answer, and you can supply a critic_prompt for domain-specific judgment. If you do, include the required placeholders {query}, {expected_answer}, and {actual_answer}; omitting them is a documented cause of the custom prompt having no effect.
Version the test set alongside the agent configuration. Source control for data agents is in preview and stores schema selection, AI instructions, data source instructions, and example queries as structured files in Git, with diff, history, and revert (source control). Re-run evaluation whenever instructions, schema selection, or the forecast table change — and treat a configuration change without a re-run as an untested change.
Set your own pass thresholds. A universal accuracy number would be meaningless across different series counts, horizons, and tolerance for rounding; the reader's threshold is the one that reflects the decisions the agent's answers feed.
Assign Review and Approval for Forecast Revisions
A forecast that reaches a business user through a conversational agent carries an implicit claim of authority. Approval is how that claim becomes true.
Separate three roles. The forecasting owner (or model owner) proposes the run. A domain reviewer validates the numbers against business context — promotions, supply constraints, known one-offs. A data steward confirms the revision was written with correct metadata: right series_key, right week_start, right model_version, right revision_reason. In small teams one person may hold two roles; the record should still name which role approved.
The review record should carry: forecast_run_id, the series or segment scope, prior value and new value, revision_reason, reviewer identity, approval timestamp, as_of_utc, and the model or pipeline version. Store it in a table the agent can join, so an answer can cite who approved a value and when. That join is what turns "the agent said 12,400" into "the agent said 12,400, approved by the demand planning lead on 19 October."
Enforce visibility through permissions as well as through instructions. Fabric data agents honor all user permissions to the underlying data, including row-level and column-level security, and Microsoft recommends granting only the permissions required — read access is sufficient to query a semantic model through an agent (sharing and permissions). If pending revisions should be visible only to the review group, that is a permission boundary, not a prompt.
None of this is a built-in approval workflow. Fabric does not ship a forecast-approval process; the roles, the record, and the join are yours to build. The agent's contribution is to surface only approved revisions and to make the approval record reachable.
Recognize the Common Failure Modes
These are the failures a weekly forecast agent actually produces. Each has a detection method that does not depend on the user noticing.
Ambiguous "forecast." The user means plan; the table holds the statistical forecast; the agent answers with whichever it retrieved. Detection: an evaluation question that asks for "the forecast" with no qualifier and expects a clarifying question. Fix: instructions that require disambiguation between actuals, plan, and statistical forecast.
Blank read as zero. A missing row is summed as zero, and a gap becomes a confident forecast of nothing. Detection: the known-gap test question. Fix: explicit status, NULL treated as "no forecast" in instructions, and a pipeline test that no approved row has a NULL value.
Stale as-of. The agent answers from a run older than the current week because the pipeline failed silently or the view resolves the wrong run. Detection: every answer must state as_of_utc; a scheduled check that the latest approved run is within the expected window. Fix: alert on pipeline failure; make the view select the latest approved run explicitly.
Mixed grain. Weekly and daily rows, or series keys at different hierarchy levels, are summed together. Detection: a uniqueness test on the grain, plus an evaluation question that totals a parent and its children. Fix: one grain per table; separate tables for different grains.
Week-numbering mismatch. ISO, WEEKNUM System 1, and a fiscal calendar produce three different "week 1" answers. Detection: the year-boundary and fiscal-week-1 evaluation questions. Fix: one convention, stated in data source instructions and used in the semantic model.
Timezone cutoff drift. A late-arriving Sunday record changes last week's number after the fact. Detection: compare the answer for a closed week across two days; it should not move. Fix: an explicit cutoff instant and as_of_utc on every row.
History-limited context. The 25-row cap and prior chat turns truncate a "show all" request, and follow-ups inherit the truncated context. Detection: ask for more than 25 rows and check the answer's row count and any caveat. Fix: instructions that direct bulk requests to reports or pipeline output and recommend a new chat session for a fresh pull.
Run these as a standing test set, not a one-time audit. Each maps to a question in the evaluation set from the previous section.
Acceptance Checklist for a Weekly Forecast Agent
Run these before the agent is trusted in production. Each is a check you perform; none is a platform guarantee.
Grain uniqueness test passes on (
series_key,week_start,forecast_run_id).Week convention and fiscal calendar are documented in data source instructions and match the semantic model.
Timezone cutoff is stated, and
as_of_utcis present and non-null on every row.The revision table is append-only, and a point-in-time view resolves the latest approved revision as of a timestamp.
Agent schema selection is scoped to the forecast view and dimension tables, with read-only access to the source.
Instructions forbid recomputation, require
status = 'approved'by default, requireas_of_utcin every answer, and treat NULL as "no forecast."Example queries cover each testable behavior, including the ambiguous-forecast and known-gap cases.
The evaluation test set is versioned with the agent configuration in Git and passes at your threshold.
An approval record exists for every revision the agent can surface, and the record is joinable from the answer.
Failure-mode tests for blank/zero, stale as-of, mixed grain, week numbering, and the 25-row cap have been run and pass.
Frequently Asked Questions
Can a Fabric data agent generate a weekly forecast on its own?
No, by design. Microsoft's documentation states the agent retrieves and processes structured data from the user's query and does not perform advanced analytics, machine learning, or causal inference (create a Fabric data agent). A forecast must be produced by a separate engine and stored where the agent can read it.
Which week-numbering convention should the agent use?
The choice is yours, but it must be pinned. ISO 8601 weeks start Monday, and the ISO week-year is the year containing the Thursday (ISO week date). DAX WEEKNUM defaults to Sunday-start System 1 unless return_type 21 is used (WEEKNUM). State the convention in data source instructions so SQL and semantic-model answers agree.
How do I stop the agent from reporting a missing forecast as zero?
Carry an explicit status in the data contract and instruct the agent to treat NULL as "no forecast." Add an evaluation question for a series with a known gap and check that the answer says "no forecast" rather than 0.
Why does last week's forecast number change when I re-ask?
Revisions and as-of timestamps explain it. If the agent queries the latest revision without an as-of filter, the number moves when a revision lands. Query a point-in-time view and require the as-of timestamp in the answer.
Does the agent return every row I ask for?
No. Microsoft documents that responses are capped at 25 rows and 25 columns and that prior chat history can influence later answers (concept). For a full weekly dataset, use the pipeline output directly; use the agent for conversational checks.
How do I test the agent before trusting it?
Define ground-truth pairs in a DataFrame, run evaluate_data_agent through the Fabric SDK, and review summary and step-level results, optionally with a custom critic_prompt (evaluate your data agent). Version the test set with the agent configuration in Git.
Who should approve a forecast revision?
That is an organizational decision, but the record should be explicit: who approved, when, why, and which run and model version. Separating proposal, domain review, and data-steward confirmation keeps each check accountable, and surfacing only approved revisions to the agent keeps the conversational layer consistent with the governance record.