
Medallion Architecture: What Changes Between Bronze, Silver, and Gold?
A worked order-data trace through Bronze, Silver, and Gold: what each layer changes, how Gold feeds BI, and why the layers are logical, not three storage systems.
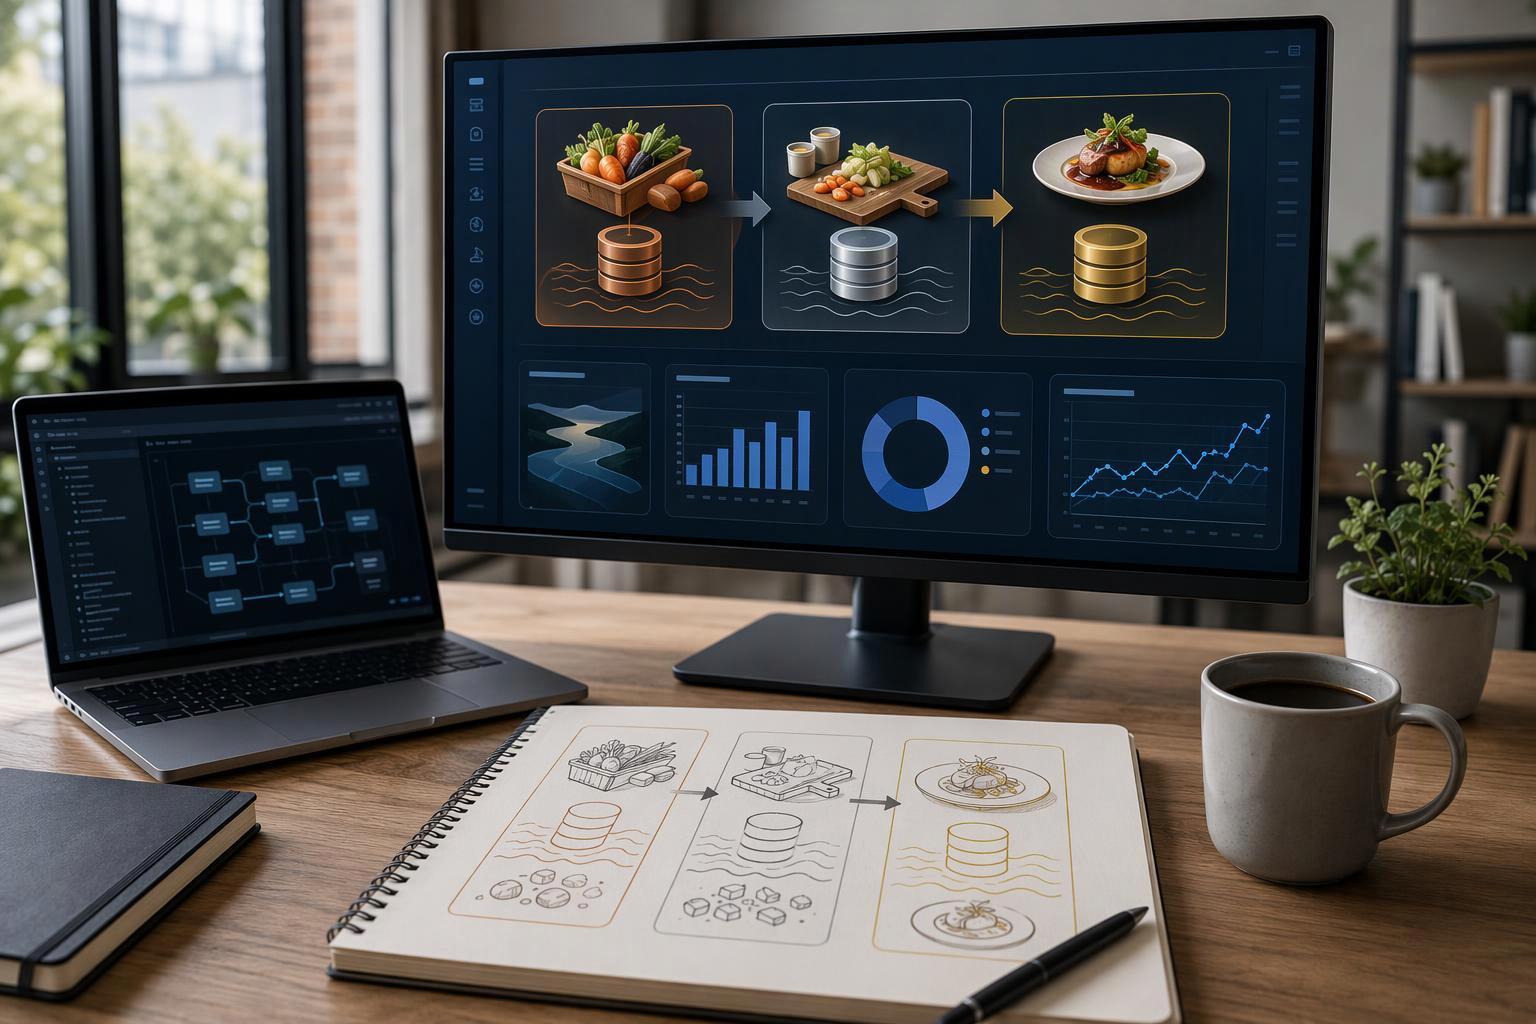
A restaurant kitchen receives deliveries, preps ingredients, and plates dishes. Nobody confuses the loading dock with the pass, yet all three can operate under one roof. Medallion architecture works the same way: Bronze, Silver, and Gold describe how ready data is for use, not where it is stored.
This article follows one order record through all three layers. It names what changes at each boundary, shows how Gold feeds BI, and corrects the assumption that three layers require three separate storage systems.
The Analogy: A Kitchen, Not Three Warehouses
Deliveries arrive in crates. The labels come from the supplier, some items are damaged, and the same shipment may be delivered twice after a retried dispatch. The receiving station logs what arrived and when, and does not throw away the damaged boxes — they are evidence of what the supplier actually sent. That is Bronze.
The prep station washes, sorts, and portions ingredients into standard units: grams, liters, trimmed cuts. It discards nothing it cannot account for, but it does resolve ambiguity — the crate labeled "12 ct" becomes a known count, the ambiguous date stamp becomes a specific delivery date. That is Silver.
The pass plates dishes for a specific menu and a specific table. A dish is not a smaller pile of ingredients; it is a different object, shaped by what a diner ordered. That is Gold.
Each station exists because the next one cannot do its job on the previous one's output. The pass cannot plate from crates, and the prep station cannot portion ingredients that were never logged. The stations are roles, not buildings — one kitchen can run all three.
What Each Layer Actually Changes
Databricks describes medallion as a series of layers that denote data quality, with Bronze for raw ingestion, Silver for cleaning and validation, and Gold for dimensional modeling and aggregation. Microsoft's Fabric reference architecture uses similar language: Bronze as the raw system of record, Silver as cleansed and conformed data, Gold as consumption-ready star schemas and pre-aggregates.
Bronze | Silver | Gold | |
|---|---|---|---|
What enters | Source data as delivered, including invalid records | Bronze tables, one or more | Silver tables |
What leaves | Raw records plus ingestion metadata | Validated, deduplicated, typed entities at transaction grain | Facts, dimensions, aggregates shaped for a business question |
Who consumes it | Data engineers, data operations, compliance and audit | Data engineers, analysts needing detail, data scientists | BI developers, business analysts, executives, operational teams |
What is deliberately not done | Business logic, filtering, deduplication, enrichment | Business-specific aggregation and presentation modeling | Re-implementing source-level cleanup |
Two scope notes matter before the details. Databricks states plainly that following medallion is "a recommended best practice but not a requirement," and its own data modeling guidance calls medallion a reference architecture whose layers can be added or removed as needed. The pattern is a starting point, not a compliance regime.
Bronze: Preserve the Record, Resist the Urge to Fix It
Bronze's job is fidelity. The Databricks medallion documentation describes Bronze as containing and maintaining the raw state of the source in its original formats, appended incrementally, retaining all historical data so it can be reprocessed and audited. It is intended for the workloads that build Silver, not for direct analyst access.
The practices follow from that job. Store most fields as string, VARIANT, or binary so an unexpected schema change does not drop data. Add metadata columns such as the source file name or load timestamp. Keep invalid records rather than filtering them out. Microsoft's Fabric guidance adds the same points: Bronze captures source data without applying business logic, closely mirrors source schemas, and intentionally avoids filtering, deduplication, or enrichment, with optional ingestion timestamps and source identifiers for auditing.
The payoff is replay. If a Silver rule turns out to be wrong — a status mapping that mislabels refunds, a deduplication key that collapses two legitimate orders — you can rebuild Silver from Bronze without going back to the source system, which may no longer hold the original state. Bronze is the audit substrate and the replay substrate at once.
Silver: The Boundary Where Types, Duplicates, and Statuses Change
Silver is where "cleaner data" becomes a list of specific operations. Databricks lists the following as performed in Silver tables: schema enforcement; handling of null and missing values; data deduplication; resolution of out-of-order and late-arriving data; data quality checks and enforcement; schema evolution; type casting; and joins.
Modeling decisions also begin here. Nested or semi-structured data has to be represented somehow — as VARIANT, as JSON strings, as structs and arrays, or flattened and normalized into multiple tables. Microsoft's guidance adds two operational requirements: transformations should be idempotent, and where historical analysis matters, Silver tables should retain row versions with effective dates and a current-row indicator, which Gold dimensions can later use for slowly changing dimension behavior.
Databricks also warns against writing to Silver directly from ingestion, because schema changes or corrupt records in the source will surface as pipeline failures. Silver reads from Bronze. That separation is what lets a malformed payload land safely and be handled deliberately rather than breaking the load.
The result is a trustworthy entity — a customer, an order, a product — but still at transaction grain. Silver answers "what happened," not "what does the business want to know."
Gold: Modeling for the Question, Not the Record
Gold is the only layer whose schema is justified by a business question rather than by a source system. Databricks describes Gold as highly refined views that drive analytics, dashboards, ML, and applications, often aggregated and filtered for specific time periods or regions, with datasets that map to business functions. Modeling here means dimensional models: relationships established and measures defined, so an analyst with Gold access can find domain data and answer questions.
The layer is not necessarily singular. Because Gold models a business domain, some organizations create multiple Gold layers for different needs such as HR, finance, and IT. Aggregates are common — a materialized view that pre-aggregates weekly bookings and revenue so analysts do not rebuild the same query — and performance optimization is a stated best practice because these tables are queried frequently. Microsoft's guidance adds that Gold tables should be derived from Silver, use stable surrogate keys so facts do not depend on mutable source keys, and be exposed to reporting tools.
Gold is where the record stops being a record and becomes a fact or a dimension.
One Order, Three Layers: A Worked Trace
The trace below is an illustrative example constructed for this article. It is not observed data from any named system, and the field names are generic.
The Raw Order Arrives
A plausible Bronze row might look like this:
Field | Value |
|---|---|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
The same order arrives twice, because the source job retried after a timeout. Both rows are kept. Nothing is cast, corrected, or removed.
Silver: Casting, Deduplicating, Normalizing
Silver applies the operations listed earlier, one at a time:
Type casting.
amountbecomes a decimal with an explicit currency code stored alongside it;order_tsis parsed to a standard time zone with the source offset recorded.Deduplication. The two deliveries are collapsed by a defined key —
order_idplus the source's own version or update timestamp — with an explicit ordering rule stating which row wins. The rule is documented, not implicit.Status normalization. The free-text status maps to a controlled set:
PENDING,SHIPPED,DELIVERED,CANCELLED,RETURNED. Unmapped values are quarantined for review rather than silently coerced.Flattening or joining. The nested customer object is either flattened into columns or resolved against a customer entity, depending on whether customer data is maintained in its own Silver table.
Quarantine. Rows that fail validation — a missing order ID, an amount that will not parse — land in a quarantine table with the failure reason, not in the trash.
The output has a stated grain. One row per order line is a different decision from one row per order, and the choice should be written down, because every downstream join depends on it.
Gold: From Order Rows to a Sales Fact
In Gold, the order may no longer exist as a row. Instead:
An order-line fact carries the measures — quantity, net amount, discount — keyed to customer, product, and date dimensions through surrogate keys.
A daily revenue view pre-aggregates net revenue by day, region, and product category.
The individual order is not visible in the daily revenue table. That is the point, not a loss: the question "how did the Northeast perform last quarter" does not need order-level rows, and materializing them would make the query slower. The detail remains in Silver for anyone who needs to drill down, and Bronze still holds the original payload if the Silver rules themselves need revisiting.
Why BI Queries Gold, Not Bronze
Bronze's schema mirrors its sources. If a dashboard queried Bronze directly, every report would have to re-implement the casting, deduplication, and status mapping from the worked trace — and each team would implement them slightly differently. Two dashboards would disagree about last month's revenue, and neither would be obviously wrong.
Gold encodes those decisions once. It presents facts, dimensions, stable surrogate keys, and pre-aggregates in the shape BI tools expect. Microsoft's Fabric guidance describes the connection mechanism directly: Power BI consumes Gold data through semantic models, and Gold is designed around star schemas, domain-specific data marts, and pre-aggregated summary tables to support performant querying. The semantic model sits on Gold tables, defines measures over them, and dashboards query the model rather than the raw tables.
The governance angle is a documented pattern rather than a technical necessity. Microsoft's reference architecture describes a global enterprise enforcing separation of duties by exposing only Gold tables to analytics teams while platform teams manage ingestion and transformation — avoiding uncontrolled access to raw or intermediate data. Databricks' governance guidance similarly recommends organizing Bronze, Silver, and Gold as separate schemas within each domain catalog, which makes layer-level access control straightforward.
Querying Bronze from BI is not forbidden. It is a decision to duplicate business logic in every report, and to accept that the duplicates will drift.
Do You Need Three Separate Storage Systems?
The layers are logical. The same platform can host all three, and the reference implementations do exactly that.
Databricks' example stores each layer in a different schema of one catalog — ops.bronze, ops.silver, ops.gold. Its governance guidance recommends creating schemas for the three layers within each domain catalog. Microsoft's Fabric reference architecture goes further: it implements all three layers in Fabric Data Warehouse, one warehouse product, with the layers separated by schema or by warehouse within a workspace. Microsoft's workspace guidance lays out the options explicitly — separate workspaces per layer, separate warehouses within a single workspace, or a hybrid — and states that the choice depends on organizational scale, security requirements, team structure, and governance maturity. Separate workspaces are recommended when strong security boundaries, clear ownership, or strict separation of responsibilities are required.
A practical decision frame follows from that:
Separate physical isolation when a regulatory boundary, a data residency requirement, or an ownership split between business units demands it — for example, isolating raw ingestion from curated business data.
Shared platform with schema-level separation when those boundaries do not exist. This reduces management overhead and simplifies cross-layer development and testing while preserving logical separation.
One storage layer with open table formats is a common way to get logical separation without three copies of infrastructure. A lakehouse keeps one copy of the data in open formats and applies compute and access control per layer.
The pattern describes a progression of quality. It does not prescribe three clusters.
Trade-offs and When to Deviate
Retaining Bronze in full has a storage cost, and it buys replay and audit. The trade-off is real but usually asymmetric: the cost of re-reading a source system that has already overwritten its history is not a storage bill, it is a data loss event. Where retention rules require deletion after a fixed period, that policy applies to Bronze like any other store, and the replay window shrinks accordingly.
Maintaining three transformation stages has an operational cost too. Each boundary is a pipeline to schedule, monitor, and debug, and each is a place where a schema change can break something. Teams with simple sources and small teams often collapse layers — skipping Silver entirely and building Gold directly from Bronze is a legitimate choice when the source is already clean and the business logic is thin. Microsoft's own guidance notes that its SQL-first architecture is one option among several, and that a lakehouse-first approach may fit better for Spark-based or unstructured workloads.
Adding layers is equally legitimate. Multiple Gold domains, historization requirements, or strict separation of duties can justify more stages, not fewer. Databricks frames the decision around company size and complexity, regulatory requirements, usage patterns, and team structure — larger organizations often need more layers; compliance needs may dictate additional controls.
The consistent principle is progressive refinement: each layer should improve structure or quality in a way the next consumer needs. A layer that only copies its input adds cost without adding readiness.
Common Misconceptions
"Three layers means three systems." The layers are logical. One catalog with three schemas, or one warehouse with three schemas, satisfies the pattern. Physical separation is a governance decision, not a definitional requirement.
"Bronze should be cleaned a little." Bronze preserves the source as delivered, including invalid records. Cleanup belongs in Silver, where it can be tested, versioned, and reversed without losing the original.
"Silver is Bronze with fewer nulls." Silver changes types, resolves duplicates and late-arriving data, normalizes statuses, enforces quality rules, and begins modeling. It is a different contract, not a filtered copy.
"Gold must contain every record." Gold is modeled for questions. Aggregates and filtered datasets are expected, and the detail remains available in Silver.
"Medallion is mandatory." Databricks calls it a recommended best practice and a reference architecture whose layers can be added or removed. It is a starting point to adapt.
An Acceptance Checklist Before You Build
Bronze retains invalid records and adds ingestion metadata such as load timestamp and source identifier.
Bronze fields are stored in types that survive unexpected schema changes — string, VARIANT, or binary where appropriate.
Silver contains at least one validated, non-aggregated representation of each record.
Deduplication keys and ordering rules are documented, not implicit in the code.
Silver transformations are idempotent, so a re-run produces the same result.
Where history matters, Silver retains row versions with effective dates and a current-row indicator.
Every Gold table traces to a named business question or domain.
Gold dimensions use stable surrogate keys rather than mutable source keys.
Access controls match layer sensitivity — broad access to Gold, restricted access to Bronze and Silver.
The physical layout decision (shared platform versus separate isolation) is documented with its rationale.
FAQ
Can a layer be skipped?
Yes. Databricks describes medallion as a reference architecture whose layers can be added or removed as needed. Skipping Silver and building Gold directly from Bronze is workable when the source is already clean and the business logic is thin; the cost is that every cleanup rule then lives in the Gold pipeline, where it is harder to reuse.
Does medallion work with streaming data?
Yes. Databricks states that medallion supports both batch and streaming data, and its Bronze layer can ingest from message buses such as Kafka alongside cloud object storage and federated systems. The layers describe quality progression, not ingestion cadence.
Where do machine learning workloads read from?
Databricks lists data scientists as intended users of both Silver and Gold. Silver suits model building and advanced analytics that need detailed, non-aggregated records; Gold suits feature tables and consumption-ready datasets. The choice depends on whether the model needs transaction detail or business-level aggregates.
Is medallion the same as a data warehouse?
No. Medallion is a design pattern for organizing data by quality; a data warehouse is a system that stores and serves it. A warehouse can implement medallion with schemas, and a lakehouse can implement it with open table formats — the pattern does not dictate the product.