How Singdata Addresses the Text-to-SQL Hallucination Problem
A three-part look at Text-to-SQL hallucination: what the published error studies show, the safeguards Singdata applies — semantic layer modeling, metadata validation, pre-execution logic checks, and feedback loops — and the benchmark and customer evidence a buyer should demand before trusting an accuracy claim.
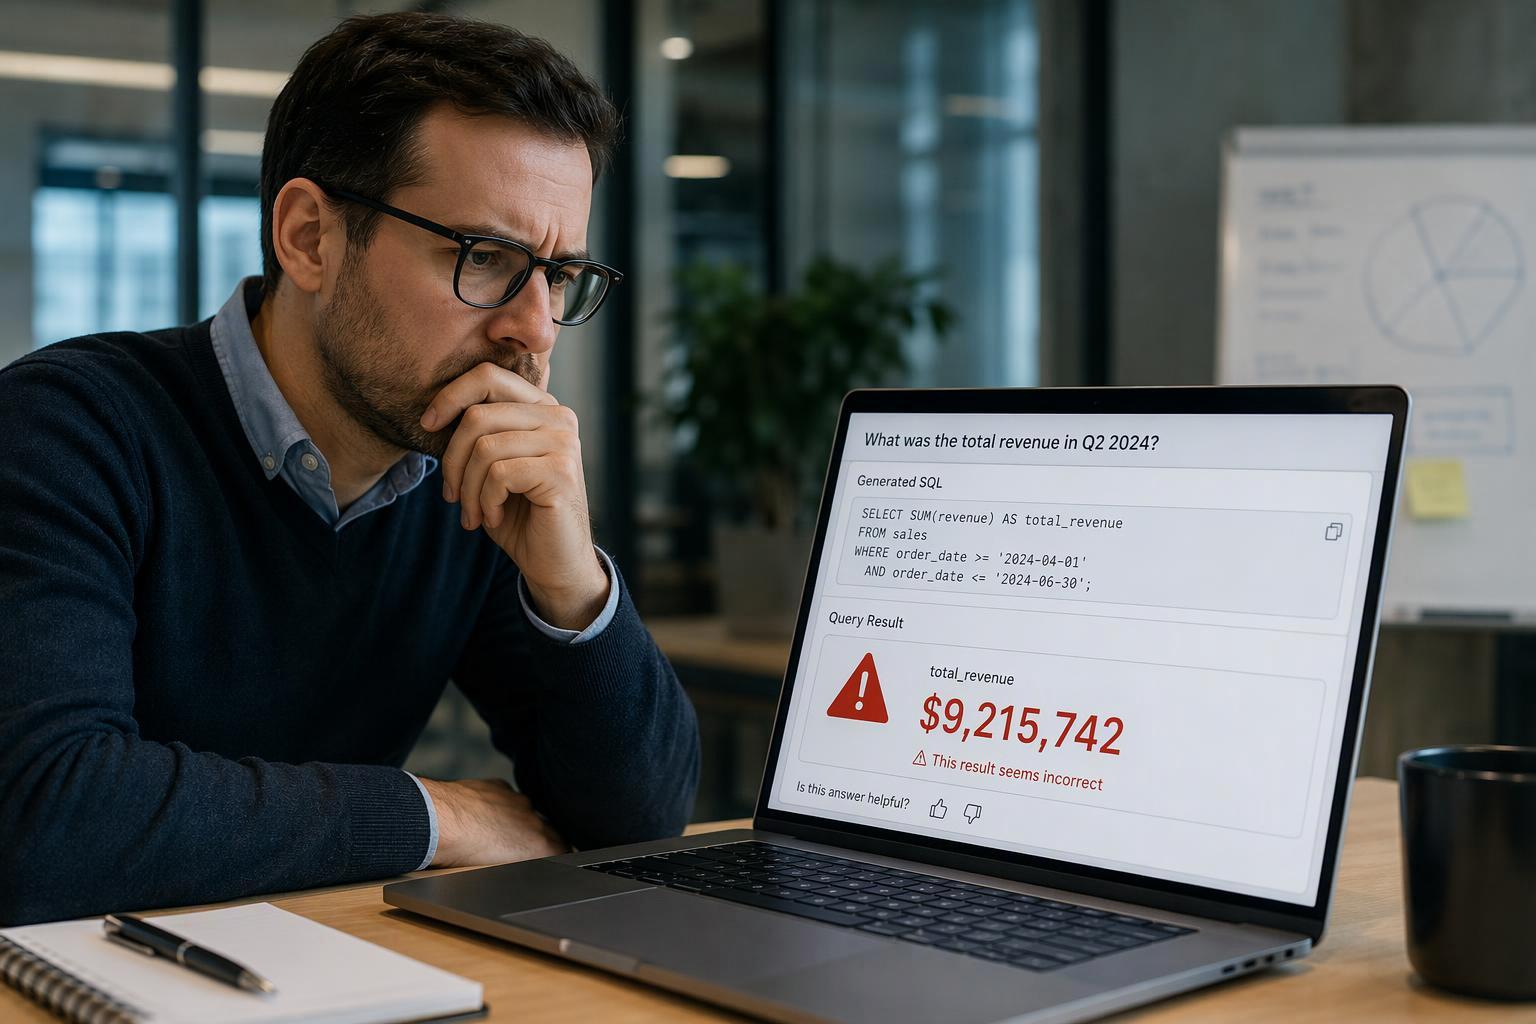
A natural-language query tool that returns a confident, executable, wrong number is harder to catch than one that throws an error. The SQL runs, the dashboard renders, and the figure enters a board deck. That failure mode — Text-to-SQL hallucination — is the subject of this article, and it is organized in three parts: an honest account of what the failure looks like and why it happens, the specific safeguards Singdata applies to it, and the evidence a buyer should demand before trusting any vendor's accuracy claim.
One boundary up front. Published benchmark figures below are cited to their sources with test conditions. Singdata-specific accuracy figures and customer outcomes are not publicly established, so they appear as clearly marked placeholders rather than estimates. Treat them as the questions to put to Singdata during evaluation.
Part 1: Text-to-SQL Hallucination Is a Real, Unsolved Problem
Text-to-SQL hallucination is not a fringe defect. A study of four in-context-learning Text-to-SQL techniques across two benchmarks and two model settings found that 37.3% of generated queries contained errors, summarized into 29 error types across seven categories; on BIRD, 47.8% of the 6,136 generated queries with a reliable correctness judgment contained at least one true error (Shen et al.). Roughly a quarter of those errors were format-related — detectable without even reading the question or the schema.
Share of classified errors by category in Shen et al.'s study of four in-context-learning Text-to-SQL techniques. Percentages are shares of classified errors (n=2,620 on BIRD, n=1,035 on Spider), not shares of queries; the study reports 47.8% of judged BIRD queries and 26.8% of Spider queries as erroneous.
What it looks like in practice
The published taxonomy is useful because each category has a recognizable signature in production (Qu et al., ACL Findings 2024):
Schema contradiction — the query references a table or column that does not exist, or omits a join the question requires. In the paper's example, a question about card sets needs a join to a translations table; the generated SQL queries one table and silently drops the join.
Attribute overanalysis — asked "which player is the tallest," the model returns the player name and the height column, contradicting the requested result format.
Value misrepresentation — the model invents a plausible but nonexistent value format, filtering on
'M'where the stored value is'Male'.Join redundancy — extra tables are joined into an already-correct query, adding cost and risk without adding meaning.
Clause abuse — a
GROUP BYis inserted where the question wanted an ordered top-1, changing which row survives the limit.Mathematical delusion — the model invokes a function that does not exist, such as
DIVIDE(a, b)instead of the/operator.
The distinction that matters most to a data leader is the last mile of that list. A query can execute cleanly and still answer a different question than the one asked. Nothing in the database rejects it, because the database only checks syntax and schema — not intent.
Why it happens
Three structural causes account for most of it.
The model lacks reliable schema context at enterprise scale. Spider 2.0, built from real enterprise workflows with databases often exceeding 1,000 columns, reports that an o1-preview agent solved 91.2% of Spider 1.0 tasks but only 21.3% of Spider 2.0 tasks (Lei et al., ICLR 2025). The skill does not transfer, because the enterprise problem is finding the right metadata, not writing SQL. LinkedIn's enterprise deployment shows the same lever from the other direction: adding metadata context reduced schema hallucination from 23% to 1% and compilation errors from 34% to 4% (Chen et al.).
Business definitions are ambiguous or undocumented. When "active user" or "revenue" has no governed definition, the model improvises one — a defensible-looking COUNT(DISTINCT ...) that matches nobody's board metric.
Generated queries are frequently not validated before execution. Pre-execution checks against the query text and schema catch schema-level errors cheaply, before any rows are scanned; skipping them pushes the discovery to a human reading a wrong number (FutureAGI).
A caution on evidence: execution success is not analytical correctness, and benchmark ground truth itself carries annotation error. A CIDR 2026 analysis found annotation errors in 52.8% of BIRD Mini-Dev problems and 66.1% of Spider 2.0-Snow problems, and re-evaluation shifted agent rankings by up to three positions (Jin et al.). "We score well on BIRD" is therefore a starting point for a conversation, not proof of enterprise reliability.
Part 2: Singdata's Technical Safeguards
The safeguards below are described at the level of function: what each mechanism does, which hallucination class it targets, and how it operates. Measured effectiveness belongs in Part 3.
Semantic Layer Modeling
Business metrics, dimensions, and relationships are defined once in a governed semantic layer and reused across queries. The model's task shifts from inferring meaning out of raw table and column names to mapping a natural-language question onto an existing governed definition. A question about monthly active users resolves to a pre-defined metric with a fixed denominator and time grain, rather than to whatever COUNT(DISTINCT user_id) the model improvises that afternoon.
This targets misread business metrics and the wrong-join errors that come from guessing at undocumented relationships. The honest boundary: a semantic layer only covers what has been modeled. Questions outside that coverage still need a fallback path, and the size of the modeled surface is a legitimate evaluation question.
Metadata Validation
Before execution, the generated query's identifiers are resolved against the live catalog — table existence, column existence, data types, and the querying user's permissions. Any unresolved reference blocks execution at the validation layer rather than failing at the database, and a query that would exceed the user's access boundary is rejected rather than trimmed.
This catches schema contradictions: nonexistent tables, columns, and functions, plus privilege violations. It is the cheapest class of check available, because it runs against query text and schema before any rows are scanned.
Pre-execution Syntax and Logic Checks
Parsing and validation go beyond syntax checking. The query is parsed into a structured form and checked for dialect correctness and clause-level logic problems: aggregation without grouping, LIMIT used where ties require RANK, COUNT where COUNT(DISTINCT ...) was meant. Defects are corrected or rejected before the query reaches the database.
This targets clause abuse, join redundancy, and mathematical delusion. Be clear about the limit: these checks catch structural defects, not semantic disagreement with what the user meant. That gap is what the next layer addresses.
Feedback Loops, Example Libraries, and Human Review
Three mechanisms work as one layer. A curated library of validated question-SQL pairs is retrieved as few-shot examples for similar questions, reducing value misrepresentation and join errors by showing the model how comparable questions were answered correctly. A feedback loop captures corrected queries and user rejections and reuses them, so the same mistake is not regenerated next week. Human-in-the-loop review routes high-stakes or low-confidence queries to a person before the number is published.
Published enterprise evidence supports the example-library mechanism specifically: LinkedIn reported that correct or near-correct responses rose from 9% to 49% when example queries, table clusters, and column attributes were added to schema-only context. Human review is a control, not a substitute for automated checks — it catches what automation flags, and it does not scale to every query.
Part 3: Data and Evidence
The evidentiary standard here is simple: published benchmark figures are cited to their sources with test conditions and dates; Singdata-specific accuracy and customer outcomes are not publicly established and remain visible placeholders. Read each placeholder as an open question for evaluation, not as an omission to be filled by assumption.
Benchmark results
BIRD's public leaderboard gives the context a buyer needs. Baseline models sit well below the top of the table: GPT-4 at 54.89% test execution accuracy, Claude 4.5 Sonnet at 66.85% on the new dev set, and Qwen3-Coder-480B-A35B at 68.14% on new dev. Leading agents with Oracle Knowledge reach the low-to-mid 80s — AskData (AT&T) at 83.40%, GrainSQL at 82.95%, Huawei's DataGallery-Text2SQL at 82.39% — against human performance of 92.96% (BIRD leaderboard).
Two caveats travel with those numbers. Leaderboard entries marked with Oracle Knowledge receive the evidence hints; production systems do not. And as the CIDR 2026 analysis showed, annotation error moves scores materially. Neither caveat makes the leaderboard useless; both make it a screening tool rather than a purchase decision.
The Singdata comparison, in the requested form:
[DATA NEEDED: Singdata execution accuracy on BIRD test set, with model, date, and Oracle Knowledge setting]
[DATA NEEDED: Singdata execution accuracy on Spider 2.0, with test conditions and date]
No Singdata figure is estimated or interpolated here.
Comparison table
Approach | Accuracy | Hallucination Rate | Notes |
|---|---|---|---|
Raw LLM | GPT-4 baseline: 54.89% on BIRD test (leaderboard) | [DATA NEEDED: measured hallucination rate for raw LLM on Singdata's evaluation set] | No schema context beyond the prompt; errors surface at execution or not at all |
LLM + Schema | [DATA NEEDED: accuracy with schema-only context on Singdata's evaluation set] | LinkedIn reports schema hallucination reduced from 23% to 1% with metadata context (Chen et al.) | Schema context is necessary but not sufficient; metric semantics remain ungoverned |
Singdata | [DATA NEEDED: Singdata execution accuracy, with benchmark, model, date, and settings] | [DATA NEEDED: Singdata hallucination rate, with measurement definition] | Semantic layer plus pre-execution validation; coverage bounded by what is modeled |
Read the table as a framework for your own test, not a like-for-like ranking. Accuracy and hallucination rate are measured on different bases across rows — different benchmarks, different model versions, different definitions of "incorrect" — and the Singdata cells are open. The useful move is to run all three approaches against your own schema and a set of questions your analysts already answer correctly.
Customer evidence
The required structure, with each element marked:
[DATA NEEDED: customer name or industry]
[DATA NEEDED: use case]
[DATA NEEDED: measurable result, e.g. reduction in incorrect query results, with measurement method and date]
Optional: [DATA NEEDED: short customer quote, with attribution and approval to publish]
A credible submission would state the baseline (what the error rate was before), the measurement window, and the definition of "incorrect" — whether that means execution failure, disagreement with a certified answer, or a user-reported rejection. Without those three, a percentage reduction cannot be interpreted.
Key Takeaways
Hallucination in Text-to-SQL is a documented, measured failure mode, not a vendor talking point: published error studies put erroneous query rates at 37.3% across settings and 47.8% on BIRD.
The safeguards that matter most act before execution — metadata validation and logic checks catch schema contradictions and clause abuse before any rows are scanned.
A semantic layer's value is bounded by its coverage; ask what percentage of your priority questions fall inside the modeled surface and what happens outside it.
Benchmark scores do not predict enterprise performance, and the benchmarks themselves carry annotation error; validate any claim against your own schema and questions.
The placeholders in Part 3 are the specific requests to make of Singdata: BIRD and Spider 2.0 results with settings and dates, a hallucination-rate definition, and at least one customer case with baseline and measurement window.
Frequently Asked Questions
Does a semantic layer eliminate hallucination? No. It reduces the class of errors that come from guessing at metric definitions and undocumented joins. Questions outside the modeled coverage still need a fallback path, and structural errors still require validation.
How do pre-execution checks differ from retrying a failed query? A retry reacts to a database error after execution. Pre-execution checks resolve identifiers against catalog metadata and inspect clause logic before the query runs, so they catch queries that would have executed successfully while answering the wrong question.
Do benchmark scores predict enterprise performance? Weakly. Spider 2.0's drop from 91.2% to 21.3% between academic and enterprise-style tasks, and the annotation-error findings in BIRD and Spider 2.0-Snow, both argue for testing on your own data.
What should we request from Singdata to replace the placeholders? BIRD and Spider 2.0 execution accuracy with model, date, and Oracle Knowledge setting; a written definition of how hallucination rate is measured; and one customer case with baseline, measurement window, and definition of "incorrect."
How does human review fit without becoming a bottleneck? Route only high-stakes or low-confidence queries to reviewers, and feed every correction back into the example library so the same question does not need review twice.