
Verifiable SQL: A Buyer's Guide to AI Text-to-SQL Tools That Can Prove Their Answers
A procurement framework for AI text-to-SQL: pass/fail gates, evidence artifacts you can check yourself, acceptance tests on your own schema, permission and ambiguity testing, and a scoring model for comparing candidates.
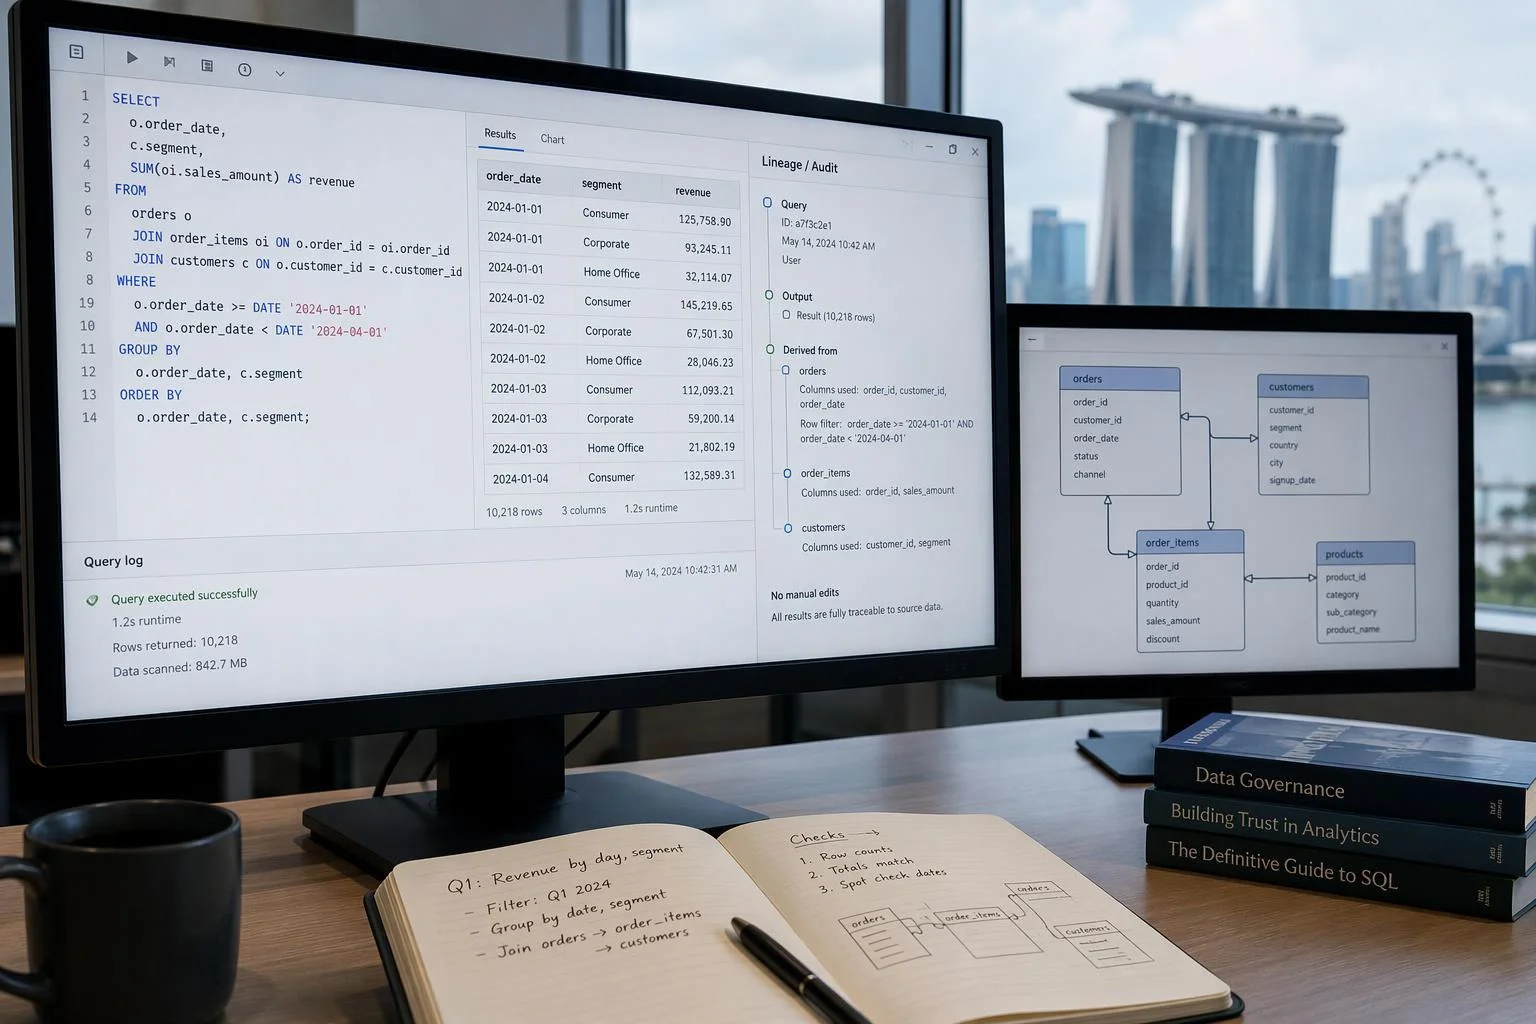
A text-to-SQL tool that returns a clean, plausible, fast-running answer has demonstrated that it can produce SQL. It has not demonstrated that the SQL answers the question asked. Those are different capabilities, and only the second one is worth paying for.
This guide is a buyer's framework, not a tutorial on checking a single query. Its companion piece covers how to prove one query returned the right answer; here the question is what to demand from a vendor before signing, and how to test whether the demand is met. The route runs from your own requirements, through a definition of provability, to pass/fail gates, evidence artifacts, acceptance tests on your schema, permission and ambiguity testing, a scoring model, red flags, and a decision procedure.
Start With Your Own Requirements, Not the Demo
Every criterion later in this guide is only as useful as the requirement it serves. Define those requirements before the first demo, because a vendor's demo is built to show the questions its system handles well, and your environment is defined by the questions it handles badly.
Start with scope. Which schemas, domains and business definitions must the tool cover on day one, and which can wait? A system evaluated on a handful of well-named public tables is being tested on a different problem from one that must resolve hundreds of tables, cryptic column names, and metric definitions that live in a wiki rather than in the schema. The BEAVER benchmark, built from private data warehouses, describes exactly this gap: 9,128 question-SQL pairs over 812 tables across 19 domains, drawn from real query logs rather than clean public schemas.
Then characterize the questions. How much domain knowledge do they require — status codes, fiscal calendars, exclusion rules that no column name reveals? How structurally complex are they: multi-table joins, window functions, nested aggregation? A tool that scores well on single-table lookups may have no path to your month-end reconciliation query.
Name the consumer and the stake. An analyst exploring a dashboard and a finance team closing a regulatory report need different levels of proof. Write down what decision rides on each answer class, and what an incorrect answer would cost. That number, not the vendor's accuracy headline, sets how much evidence you should require.
Finally, fix the permission model the tool must respect: which roles exist, whether row-level security is enforced in the database, whether the tool may write or only read, and whether it must run as the requesting user rather than a shared service account. Record these as requirements now; they become the must-have gates later.
What "Provable" Actually Means for a Text-to-SQL Tool
A query can be syntactically valid, execute without error, return a non-empty result, and still be wrong. The verification literature calls this a deceptive failure: SQL that runs but does not capture the user's intent (Alrashed et al., PVLDB 2026). It is the failure mode that matters for procurement, because nothing on the screen distinguishes it from a correct answer.
A user study of a deployed natural-language interface makes the point concretely. Most wrong answers in both study arms ran cleanly and returned a plausible, non-empty result that did not match the gold answer — 34 of 65 wrong submissions in one arm, 26 of 43 in the other. Only checking the query against the question caught them (arXiv:2511.14718).
Execution agreement is weaker evidence than it looks. Two different queries can return identical results on the data you happen to hold and diverge on another valid database state. Work on checkable query plans states the limit plainly: agreement on one database does not establish semantic equivalence, and bounded searches for a distinguishing database can support equivalence only within the encoded model and bound (VeriPIE, arXiv:2610.17493).
So "provable" for a text-to-SQL tool means something narrower than mathematical proof. It means the tool produces evidence about how an answer was produced, and that a buyer can independently examine that evidence. The evidence classes are: the resolved SQL actually executed, the execution plan, the version of the semantic definitions and schema in force, the permission context the query ran under, the data snapshot, and a result fingerprint. The rest of this guide separates the ones you can check from the ones you must take on trust.
Mandatory Capabilities as Pass/Fail Criteria
Treat these as gates, not scores. A candidate that fails any one of them is out, regardless of how well it performs elsewhere, because each failure removes a check the buyer would otherwise be able to run. The five below are the minimum set; the framework is this guide's evaluation standard, not a vendor certification or an industry benchmark.
1. Exposes the resolved SQL it executed. Pass: for any pilot question, the tool returns the exact statement sent to the engine, and you can read and re-run it. Fail: it shows a summary, a template, or a natural-language explanation in place of the statement, or releases the statement only through vendor support.
2. Records the semantic definitions and schema version in force. Pass: each answer carries an identifier for the metric definitions and schema version it was resolved against. Fail: answers reference "current" definitions with no version, so a later answer cannot be traced to the same state.
3. Runs under the requesting user's permission context. Pass: the statement executes as the user who asked the question, and row-level security filters rows accordingly. Fail: every question runs as one shared privileged service account, leaving enforcement to the application layer.
4. Can abstain or flag ambiguity. Pass: on a genuinely ambiguous question the tool surfaces the ambiguity, asks for clarification, or presents the competing readings. Fail: it returns a confident answer to every question with no way to decline.
5. Produces a reproducible result artifact. Pass: the answer carries a snapshot identifier or result fingerprint that lets you re-run it and obtain the same result. Fail: results cannot be tied to a data state, so a discrepancy cannot be diagnosed.
The Evidence Artifacts to Demand — and Which You Can Check Yourself
Request each artifact below in writing, and ask which of them you can verify without the vendor's cooperation. The distinction between checkable and trust-based evidence is the whole point of the exercise.
Resolved SQL. Checkable. You can read it, run it yourself against a copy of the schema, and compare results. This is the single most valuable artifact, because everything else is commentary on it.
Execution plan. Checkable, but narrow. It shows how the engine ran the query — scans, joins, filters — which is useful for performance and for spotting a missing predicate. It does not show whether the logic matched the question.
Semantic-definition version. Partly checkable. If your organization owns the definitions, you can confirm which version was referenced. If the vendor maintains them, you are trusting their version history.
Permission context. Checkable through testing, not through documentation. The artifact tells you which role executed the query; only a test tells you whether row-level security actually filtered rows.
Data snapshot. Checkable if the platform exposes a snapshot identifier or timestamp. Without one, a result cannot be reproduced and a discrepancy cannot be diagnosed.
Result fingerprint. Checkable for reproducibility, and easy to over-read. A fingerprint proves the result is reproducible against a snapshot. It does not prove the query matched intent; a consistently wrong query fingerprints just as cleanly as a correct one.
Ask for a sample of each artifact from your own pilot data, not from a demo tenant.
Designing Acceptance Tests on Your Own Schema
Vendor demo data is chosen to flatter the system. Your acceptance set should be built from your own schema and your own hard questions, and the vendor should not see it before the pilot.
Source the questions from real work. Pull from query logs, analyst ticket queues, and the reports that already exist. The BEAVER authors built their benchmark this way — question-SQL pairs sourced from real-world query logs — precisely because public benchmarks with well-structured schemas and simple pairs do not represent private enterprise environments (arXiv:2409.02038). Your log is the closest available proxy for that.
Stratify deliberately. Include domain-knowledge-heavy questions, structurally complex ones, and a band of routine lookups. BEAVER isolates these dimensions because a single accuracy number hides which one is failing; its authors report that state-of-the-art agentic frameworks using an advanced model reached only 10.8% accuracy on the enterprise set, rising to 30.1% when all subtask annotations were supplied as hints.
Label expected results carefully. Benchmark annotation errors are documented and consequential. An analysis of two widely used benchmarks found error rates of 52.8% and 66.1%, and re-evaluating five leading methods on the corrected set moved results by −3% to 31% in relative terms, changing rankings (Jin et al., CIDR 2026). Have two people independently derive each expected answer, and resolve disagreements before the pilot starts.
Include near-miss cases. The failure you are buying protection against is plausible but subtly wrong SQL. Verification research builds its test sets from the mistakes of strong generators for exactly this reason, because random wrong SQL is too easy to reject (Alrashed et al.). Add questions where a missing join, an off-by-one date boundary, or a wrong status code produces a believable number.
Hold out a set. Keep a portion of the questions unseen until scoring day, so tuning cannot quietly absorb them.
Treating Vendor Accuracy and Performance Claims
A vendor accuracy figure is a hypothesis about your environment, not evidence about it. Before you weigh it, establish four things: which benchmark produced it, which schema and question distribution that benchmark used, which metric was reported, and how closely the benchmark resembles your own tables and questions.
Four published figures, four different conditions. BEAVER reports accuracy on private enterprise warehouses with and without oracle subtask hints; Spider's 12.4% is exact-match accuracy for the best model at 2018 publication on a database split; BIRD's 92.96 is human execution accuracy on its Test set. Different datasets, metrics and years — the bars are not comparable to each other, and none of them predicts performance on your schema.
Metric choice matters more than buyers expect. Exact match compares SQL text and is widely regarded as too rigid for modern model evaluation; execution accuracy compares results and is the common alternative. But execution accuracy is a noisy proxy in both directions. It can inflate a score when a semantically incorrect query coincidentally returns the reference result on a sparse database, and it can deflate a score when the benchmark's own reference query is wrong (Alrashed et al.).
Public benchmarks can also misstate enterprise performance in the other direction. BEAVER's authors note that existing benchmarks were largely built from public databases with well-structured schemas and simplistic question-SQL pairs, and that model efficacy in complex private environments "remains unproven" (arXiv:2409.02038). A high score on a clean public set tells you the tool can handle clean public data.
Annotation errors compound the problem. Verification research found that over two-thirds of what looked like generator failures on audited benchmarks actually stemmed from flawed benchmark labels (Alrashed et al.), and a separate analysis found that corrections reshuffled leaderboard positions (Jin et al.). A leaderboard rank is therefore a starting point for a conversation, not a shortlist criterion.
Performance claims deserve the same treatment: ask for the workload, the data volume, the configuration, and whether the number was reproduced by anyone other than the vendor. Then plan to reproduce it in your pilot.
Testing Permissions, Row-Level Security, and Read-Only Execution
A text-to-SQL tool that generates arbitrary SQL is a query interface into your database on behalf of every user who can type a question. Whether that is safe depends entirely on the context the generated query runs under, and that is testable.
Confirm execution context. Ask the tool to run a query as a restricted user and verify, from the database's own logs or session views, that the statement executed as that user. If everything runs as one service account, row-level security is being applied by the application, if at all, and the database is no longer your enforcement point.
Test row-level security directly. Create two users whose policies should return different row sets, ask the same question as each, and compare. In PostgreSQL, row security policies restrict which rows a user can see, and superusers and roles with the BYPASSRLS attribute always bypass them; table owners normally bypass them too unless the table is forced (PostgreSQL row security policies). In SQL Server, filter predicates silently restrict rows for reads while block predicates explicitly block writes that violate the predicate, and policies apply to all users including dbo users (Microsoft RLS documentation). In CockroachDB, if RLS is enabled but no policy applies to a given user and statement, access is denied by default (CockroachDB RLS). Each behavior is a test case, not a footnote.
Probe the bypass paths. Ask a question as a privileged role and confirm the result matches the documented bypass behavior rather than silently widening access for everyone. Then check whether a restricted user can phrase a question that induces the tool to query a table outside their scope.
Confirm read-only execution. Attempt to induce a write or DDL statement — through a question, a follow-up, or a prompt injection in a column value — and verify the engine rejects it. The tool should not hold credentials that permit writes at all.
Testing Ambiguity Handling and Abstention
A system that answers every question is not more capable than one that sometimes declines; it is less honest. Abstention is the mechanism that converts a silent failure into a visible one, and it should raise a candidate's score rather than lower it.
Build a set of genuinely ambiguous questions — ones where two competent analysts would write different but defensible SQL. "Revenue last quarter" may mean booked, billed, or recognized; "active customers" may mean logged in, purchased, or contracted. For each, record what the tool does: does it surface the ambiguity, ask a clarifying question, present both readings, or silently pick one and answer confidently?
The verification literature supports treating abstention as a feature. Selective generation, where a system uses verification signals to abstain when confidence is low, transforms silent failures into explicit abstentions that alert the user and give them a chance to correct the request (Alrashed et al.). The same work separates ambiguous questions from unanswerable ones: missing-data queries are dead ends, but ambiguous queries are conditionally answerable if the system can map the user's underlying intent.
That framing gives you a coverage-versus-accuracy trade-off to measure. In the cited evaluation, a baseline generator answered 100% of queries with a 27% error rate; adding verification signals raised selective precision to 0.831 at 0.592 coverage. A vendor reporting 100% coverage and no abstention path is reporting that it has spent its precision budget on the appearance of capability. Score coverage and accuracy together, and treat an always-answers system as a finding, not a strength.
A Practical Scoring Model for Comparing Candidates
Scoring comes after gating. A candidate that fails a must-have gate is removed from the comparison; do not let a strong score on evidence completeness offset a failure to run under your permission model. Only survivors are scored.
Score the survivors on six dimensions, weighted to reflect the requirements you wrote down first:
Evidence completeness — how many of the six artifacts are produced by default, not on request.
Independent checkability — how much of that evidence you can verify without vendor cooperation.
Acceptance-test performance — results on your held-out set, reported by question class rather than as one average.
Permission and RLS results — pass rates on the execution-context, policy, bypass, and read-only tests.
Ambiguity handling — how often the tool flags or clarifies genuinely ambiguous questions.
Operational fit — integration with your catalog, identity provider, and change management.
Weight by stake. If a wrong answer feeds a regulatory filing, evidence completeness and permission results should dominate. If the tool serves exploratory analysis where a human checks every number, acceptance-test performance and operational fit may carry more weight, and a thinner evidence trail may be acceptable.
Keep the scoring honest by writing the weights down before the pilot and refusing to adjust them afterward. A common failure is discovering that the preferred vendor scores poorly on a dimension and retroactively deciding it was never important.
Red Flags and Deal-Breakers
Red flags are distinct from failed gates. A gate is a criterion the tool does not meet; a red flag is a behavior that suggests the vendor does not want the criterion tested at all.
It will not show the SQL it executed. Without the resolved statement, nothing downstream can be verified. This is the clearest signal that provability is not a design goal.
Accuracy claims with no stated benchmark, schema, or metric. A number without provenance cannot be compared to anything, including your own results.
Demos only on clean public data. If every example uses tidy tables and simple questions, the vendor is showing you the case that already works.
No way to run under your permission model. A shared privileged account means row-level security is decorative.
No abstention path. A tool that cannot decline is a tool that will answer your ambiguous question wrongly and confidently.
Evidence artifacts that cannot be independently checked. If every artifact requires the vendor to interpret it, you are trusting a conclusion rather than examining evidence.
Pressure to skip a pilot on your own schema. Your schema is the only test that reflects your environment; a vendor arguing against it is arguing against the test.
Any one of these warrants a direct question. Two or more should end the evaluation.
How to Use the Criteria to Decide
Run the pilot in a fixed order, and stop early when a candidate fails.
Re-scoring five BIRD leaderboard agents on corrected labels moved CHESS from 62% to 81% execution accuracy and from 4th to 1st among the five; OpenSearch-SQL moved from 71% to 69% and from 1st to 3rd. The audit re-evaluated a random sample of 100 of 1,534 BIRD Dev problems (CIDR 2026). A leaderboard position is therefore a starting point for a conversation, not a shortlist criterion.
First, apply the pass/fail gates from a written questionnaire plus a short technical session. This is cheap and eliminates candidates before you spend analyst time. Second, run the acceptance tests on your held-out question set, reporting results by question class so you can see where failures concentrate. Third, run the permission, RLS, and read-only tests against a copy of your schema with realistic roles. Fourth, run the ambiguity set and record abstention and clarification behavior. Fifth, score the survivors using the weights you fixed in advance.
Then weigh the scores against the requirements from the first section. The output is not a single best tool. It is the tool whose provability matches your risk tolerance and the stakes of the decisions its answers will feed. A tool with a strong evidence trail and modest coverage may be the right purchase for a regulated reporting workflow and the wrong one for open-ended analyst exploration.
Keep the acceptance set. Re-run it after every major version upgrade, because a model change or a semantic-layer edit can move results without any visible change to the interface. The pilot is the beginning of a measurement program, not a one-time purchase test.
FAQ
Does a tool have to expose SQL to be verifiable? For practical purposes, yes. Without the resolved statement you cannot check logic, reproduce a result, or investigate a discrepancy. A natural-language explanation of the query is a summary, not evidence.
How many acceptance-test questions are enough? Enough to cover each question class you identified — domain-heavy, structurally complex, routine, and near-miss — with several examples in each. A single overall average hides the class where the tool fails, which is the class you most need to know about.
Can public benchmark scores be trusted? As a starting hypothesis only. Benchmarks differ in schema, question distribution, and metric, and documented annotation errors have shifted rankings after correction. Reproduce the claim on your own schema before relying on it.
What if a vendor will not share evidence artifacts? Treat it as a failed gate for the requirement class that depends on those artifacts, and record the refusal. If the artifacts exist but require vendor interpretation, ask for a sample from your pilot data and check what you can independently.
Is a higher-coverage tool always better? No. Coverage and accuracy trade off. Compare them together, and prefer a tool that abstains visibly over one that answers everything.
Acceptance Checklist
Carry this into vendor calls and pilots. A candidate passes only if it shows the resolved SQL it executed, records the semantic-definition and schema version in force, runs under the requesting user's permission context, can abstain or flag ambiguity, and produces a reproducible result artifact. Request the execution plan, permission context, data snapshot and result fingerprint, and mark which of them you can check independently. Build an acceptance set from your own query logs, label it carefully, include near-miss cases, and hold back a portion the vendor has not seen. Score survivors only after the gates, and treat any refusal to run a pilot on your schema, or any accuracy figure without a stated benchmark, as a reason to stop.
Previous posts
https://www.singdata.com/company
https://singdata.com/trending/powerbi-date-difference-dax-calculations/