
Web Analytics and Data Analytics Platform: The Enterprise Architecture Guide
How enterprises govern event data, identity, consent, and metric definitions across a web analytics platform and a data analytics platform, with testable evaluation criteria.
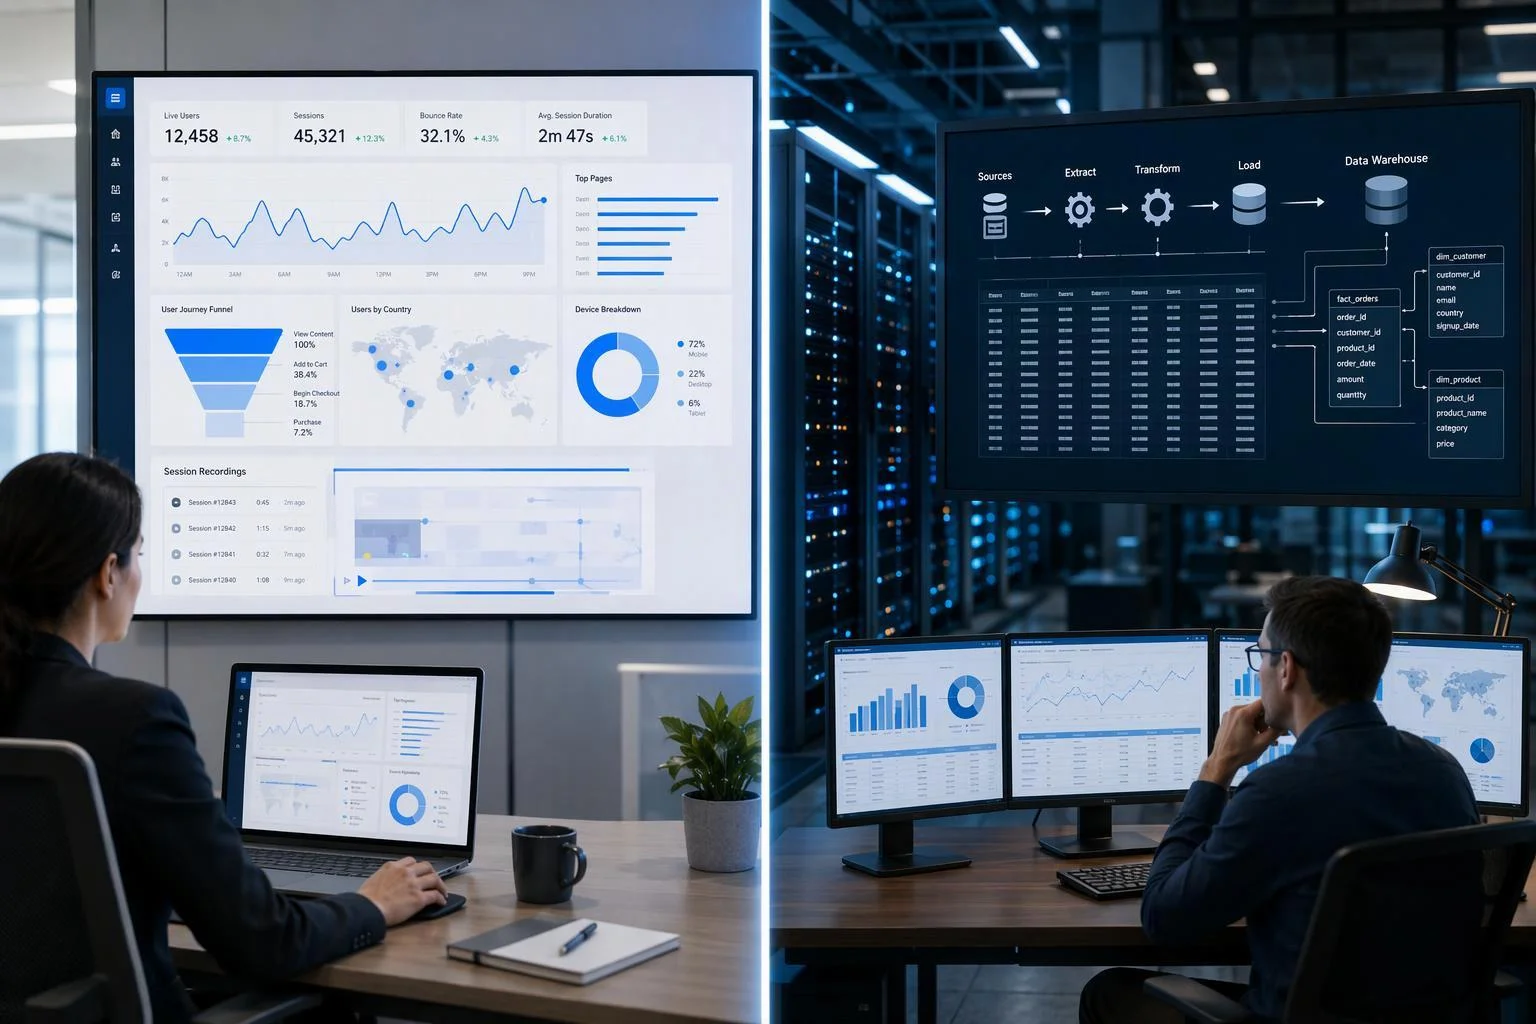
Most enterprises run two analytics systems that were never designed to agree with each other. On one side sits a web analytics platform — a collection and reporting tool built for traffic, sessions, campaigns, and audience behavior. On the other sits a data analytics platform, typically a warehouse or lakehouse, where finance, product, and operations join event data to transactions, CRM records, and offline systems.
These are different products serving different jobs, and the architecture question is not which one wins. It is how event data, identity, consent, and metric definitions are governed across both. This guide works through that question in sequence: what distinguishes the two categories, why dual-stack is the normal outcome, what fails when the two are never reconciled, how to architect collection into a warehouse, how a governed semantic layer holds definitions in place, how consent and retention obligations constrain the design, what a buyer should test, and how to detect drift in production.
Platform capabilities and regulation text change. This guide reflects sources and vendor documentation as of November 2026; recheck vendor documentation and legal text before relying on specifics.
What Is the Practical Difference Between a Web Analytics Platform and a Data Analytics Platform?
The distinction is a matter of job, not vendor category. A web analytics platform is a collection-and-reporting system optimized for session and event analysis on web and app traffic. It ships with identity resolution, attribution, audience features, and — importantly — a set of approximation and privacy behaviors that shape every number it reports. A data analytics platform is general-purpose compute and storage for joining any data under the enterprise's own definitions.
Google Analytics is the concrete reference case. Its Data API documentation describes behaviors that are inherent to the product, not defects: reports can return sampled data, and the samplingMetadatas field discloses the percentage of events used; unique counts for metrics such as Active Users and Sessions are estimated with the HyperLogLog++ algorithm, so results are approximations rather than exact counts; data thresholding can exclude rows containing a small number of users; high-cardinality dimensions may be rolled into an (other) row, and filters are applied after that aggregation; and reporting identity settings determine how users are deduplicated, so changing the setting changes user counts for the same date range (Google Analytics Data API reporting expectations).
The scope boundary follows from this. The web tool's numbers are correct answers to its own question — how many users, sessions, and conversions did this property observe, under these identity and thresholding rules. They are not a universal truth about the business, and they are not a substitute for reconciled revenue or offline joins. A warehouse answers a different question: what happened across all systems once the enterprise applies its own definitions. Treating either number as authoritative for the other's question is where most reconciliation disputes begin.
Why Enterprises End Up Running Both Platforms
The dual-stack outcome is usually rational, not accidental. Marketing needs fast, low-friction answers and the web tool's built-in attribution, audience, and ad-platform integrations — capabilities a warehouse does not replicate out of the box. Finance and product need numbers reconciled against revenue, orders, and offline data, which requires joins the web tool was never built to perform. Each team buys the tool that answers its question fastest.
The web tool's own documentation acknowledges this division of labor. Where a use case requires full, unsampled, event-level data, Google recommends BigQuery Export as the method for advanced analysis of raw event data (reporting data expectations). That recommendation presumes a warehouse exists alongside the reporting interface; the vendor is pointing advanced users to the second system rather than claiming the first can do the job.
Procurement reality reinforces the pattern. Existing contracts, sunk implementation effort, trained analysts, and agency relationships all create switching costs that rarely justify consolidation on their own. The legitimate division of labor is: the web tool owns fast operational reporting on traffic and campaigns; the warehouse owns reconciled, joinable, historically durable analysis. The problem is not that both exist. It is what happens when nothing governs the boundary between them — which is the subject of the next section.
What Breaks When Web Analytics and Warehouse Reporting Run Separately
The following failure classes are architectural reasoning, not measured findings from a study. They describe what follows from running two collection and definition systems without a reconciliation layer, and each comes with an observable symptom a team would recognize.
Definition drift. The same metric name gets computed differently in each system. A warehouse model that counts purchase events from raw exports may include events the web tool excluded, because adding dimensions to a report can result in fewer events used in calculations — only events containing data for the requested dimensions are included, so adding dimensions can alter aggregated values (reporting data expectations). Symptom: two dashboards show different conversion counts for the same date range, and neither owner can explain the gap.
Identity stitching. Reporting identity settings decide how users are deduplicated, and different settings produce different user counts for the same period (reporting data expectations). The warehouse must either reproduce that logic deliberately or diverge from it with documentation. Symptom: user counts move when a property setting changes, with no corresponding change in traffic.
Consent propagation. A consent state recorded in the tag layer or CMP never reaches the warehouse tables, so downstream models process events the user did not permit. Symptom: an audit finds events in the lakehouse with no consent attribute, or with a stale one.
Duplicate pipeline cost. Two collection paths, two transformation layers, and two on-call rotations. Symptom: the same event is transformed twice by different teams, and neither cost line is attributed to a single owner.
How to Architect Event Collection into a Warehouse or Lakehouse
The engineering sequence below moves from collection to modeled data, with a checkpoint after each stage. The order matters: validation before modeling, reconciliation before trust.
Stage 1 — Choose the collection path. Client-side tagging sends measurement data from the browser to collection servers. Server-side tagging runs a container on infrastructure you control: the server receives requests from the user's device, transforms them into events, and you decide how that data is shaped and where it is routed (introduction to server-side tagging). Google recommends installing the server on a first-party domain and running it in production mode before sending production traffic. A first-party collection endpoint gives you one controlled ingress point for both the web tool and your warehouse pipeline.
Stage 2 — Treat the Measurement Protocol as an augmentation. The Measurement Protocol sends events directly to Google Analytics servers over HTTP, covering server-to-server and offline interactions. Its documentation is explicit that its intent is to augment automatic collection through gtag, Tag Manager, or Firebase, not to replace it, and that you must use tagging to use most of its features; sending events solely through the protocol may yield only partial reporting (Measurement Protocol). Design it as a supplement for offline conversions and server-side events, not as your primary collection layer.
Stage 3 — Land raw events immutably. Write every event to a raw landing zone as an immutable record, with ingestion timestamp, source, and a deduplication key. Validate payloads against a schema contract at ingest and reject rather than silently coerce. Handle late arrivals with a bounded window and a documented policy. Checkpoint: payload validation pass rate and rejection reasons reviewed weekly.
Stage 4 — Reconcile against the source tool. Compare row counts and key metric totals between the warehouse and the web tool for a fixed date range, with sampling and thresholding disclosed on the web tool side. Checkpoint: variance within a stated tolerance, or a documented explanation for every breach.
Stage 5 — Build the modeled layer. Transform raw events into conformed models beneath the semantic layer, with identity resolution applied explicitly. Checkpoint: identity coverage rate — the share of events with a resolved canonical ID — tracked as a first-class metric.
How a Governed Semantic Layer Keeps Both Platforms Consistent
The semantic layer is the single place where metric definitions, identity rules, and dimension logic live, and where both the web tool's exports and the warehouse models are mapped to a shared vocabulary. Without it, consistency is maintained by memory and convention; with it, consistency is a property of the system.
The practical mechanics are unglamorous. A metric registry records, for each metric, an owner, a plain-language definition, the source-of-truth flag, and a change log. A mapping table links the web tool's event and parameter names to the warehouse's canonical schema, so that purchase in one system and order_completed in the other resolve to the same governed concept. Dimension logic — how sessions are bounded, how channels are classified, which date field defines attribution — is written down once and referenced everywhere.
Reporting identity settings deserve specific treatment. Because different identity settings produce different user counts for the same date range, and because the setting applies to both the UI and the API, a change to it silently shifts historical comparability (reporting data expectations). The semantic layer should record the current setting as a known divergence from warehouse identity logic, with the date of the last change, rather than attempting a silent reconciliation that hides the difference.
The test of whether the layer holds is not whether it exists but whether it constrains behavior: can a metric change be traced to an owner and a date, and can a consumer see which system produced a given number? The evaluation checklist later in this guide turns that into pass conditions a procurement team can run.
How Consent and Retention Obligations Constrain the Architecture
Privacy obligations are architectural requirements, not policy documents filed after launch. Three constraints matter most for a dual-stack design, and each spans both platforms.
Demonstrable consent. Under GDPR Article 7, where processing is based on consent, the controller must be able to demonstrate that the data subject consented, and withdrawal must be as easy as giving consent (GDPR Art. 7). Architecturally, consent state must be a first-class event attribute captured at collection and carried through storage, transformation, and the semantic layer — not a flag held only in the tag manager.
Erasure. GDPR Article 17 obliges the controller to erase personal data without undue delay on defined grounds, including withdrawal of consent where no other legal ground applies, subject to stated exceptions such as legal claims and archiving or statistical purposes under Article 89(1) (GDPR Art. 17). An erasure request must reach raw event storage, derived tables, and the web analytics property. That may require deletion APIs, export-and-purge workflows, or both — and the exceptions mean erasure is a legal determination, not a blanket delete.
Retention limitation. Singapore's PDPA, as summarized by IAPP, includes consent, purpose limitation, notification, retention limitation, and transfer limitation obligations; the retention obligation requires an organization to cease retaining personal data once the purpose is no longer served and retention is no longer necessary for legal or business purposes (IAPP, The Personal Data Protection Framework in Singapore). The PDPC's own guidance frames the same obligation in section 25 terms (PDPC Advisory Guidelines). Enforce retention schedules by policy in the lakehouse; do not assume the web tool's settings satisfy them.
Specific obligations depend on jurisdiction and the facts of your processing. The sources cited here are not a substitute for legal counsel.
What Testable Criteria Should a Buyer Use to Evaluate a Combined Stack?
Feature checklists reward vendors for claiming capabilities. The framework below instead asks what you can test, with a pass condition for each criterion, so a procurement team can run it against any combination of web analytics tool and warehouse.
Data fidelity. Reconcile a defined date range between the web tool and the warehouse for three core metrics. Pass condition: variance within a tolerance you set in advance, with sampling and thresholding disclosed on the web tool side and every breach explained.
Identity. Reproduce the web tool's user counts from raw events, or document precisely where you intentionally diverge and why. Pass condition: a written identity specification exists, and a re-run reproduces the documented counts.
Consent. Trigger a withdrawal in a test environment and confirm it propagates to both systems. Pass condition: propagation within a stated time, with an audit record proving it.
Governance. Inspect the semantic layer. Pass condition: every governed metric has a named owner, a definition, a source-of-truth flag, and a change log entry for its last modification.
Cost. Total the pipeline cost of both paths, including duplicate transformation and on-call. Pass condition: cost per collection path is attributed and visible to the owner of that path.
Exit. Request a raw event export in an open format. Pass condition: you can reconstruct your event history outside the vendor's environment without loss of the fields you depend on.
Run each test before signing and again at the first renewal. A stack that passes at procurement and fails six months later has told you something about governance, not about the products.
How to Detect Common Failure Modes in Production
Detection is engineering reasoning: each failure class from earlier in this guide has a signal, a threshold logic, and an owner. The table below turns those into monitoring obligations.
Failure mode | Signal | Threshold logic | Owner |
|---|---|---|---|
Metric drift | Scheduled reconciliation of web tool totals vs. warehouse totals | Alert when variance exceeds the agreed tolerance band for two consecutive runs | Analytics engineering |
Identity coverage | Share of events with a resolved canonical ID | Alert on a drop beyond a set percentage week over week | Data engineering |
Consent propagation lag | Time between withdrawal event and removal from downstream tables | Alert when lag exceeds the stated propagation SLA | Privacy engineering |
Pipeline duplication cost | Cost attributed per collection path | Review when duplicate-path cost exceeds a set share of total pipeline spend | Platform owner |
Schema drift | Validation rejection rate at ingest | Alert on rejection-rate spike or a new rejection reason | Ingestion owner |
Freshness divergence | Last-processed timestamps in warehouse vs. web tool | Alert when the gap exceeds the expected processing window | On-call data engineer |
Two design notes. First, thresholds should be set from observed baseline behavior, not from vendor claims; a tolerance band that ignores normal sampling variance will page constantly. Second, every alert needs a named owner and a runbook — a signal without an owner is a dashboard, not a control. Review the table quarterly and retire signals that no longer correspond to a real failure mode.
Where a Unified Lakehouse Fits — and Where It Does Not
A lakehouse with a shared semantic layer and open table formats changes the economics of the dual-stack problem: one copy of event data can serve both the session-level questions marketing asks and the joined, reconciled questions finance and product ask. That reduces the duplicate-pipeline cost described earlier, because there is one landing zone, one transformation layer, and one set of definitions rather than two.
Singdata positions its platform in this category. The vendor describes a single-engine lakehouse with one semantic layer and one set of permissions over data held in open formats in the customer's own object storage, plus a shared semantic layer that both human analysts and AI agents query against. Those are vendor-described capabilities, not independently verified outcomes; treat them as claims to test against the criteria in the previous section rather than as established results.
What a lakehouse does not do is replace a web analytics tool's attribution modeling, audience activation, or ad-platform integrations. Those are product features built on the web tool's own identity graph and media relationships, and moving event storage into a warehouse does not reproduce them. Whether the web tool stays depends on how much of that surface your organization actually uses — a question the checklist answers better than a product comparison does.
Conclusion: The Architecture Question Is Governance, Not Product Choice
The two platform categories answer different questions, and neither one's numbers are a universal truth. A web analytics platform reports on traffic under its own identity rules, sampling behavior, and thresholding; a data analytics platform reports on whatever the enterprise defines and can join. Running both is a legitimate division of labor. Running both without a governed boundary is where the failures in this guide come from.
That boundary has three working parts. A shared semantic layer holds metric definitions, identity rules, and the documented divergences between the two systems. Consent state travels as a first-class attribute through collection, storage, and the models both platforms read from. Scheduled reconciliation compares the web tool's reported totals against warehouse totals inside a stated tolerance and alerts when the gap widens.
Start with the acceptance checklist rather than a product decision. It converts each of those parts into a test with a pass condition, which is what a procurement team can actually run and what an engineering team can actually own. The FAQ below covers the specific scenarios this guide has not answered directly.
Frequently Asked Questions
Can a warehouse replace a web analytics platform entirely?
Not on data storage alone. A warehouse can hold the raw events and reproduce most reporting, but it does not carry the web tool's attribution modeling, audience activation, or ad-platform integrations. Whether replacement is viable depends on how much of that surface your teams depend on; the acceptance checklist is the way to find out rather than assuming either answer.
Why do user counts differ between the web tool's UI and its API?
Google's own documentation lists several causes: the UI and API can apply different sampling thresholds, unique counts are estimated with HLL++ rather than counted exactly, data thresholding can drop small rows, and the reporting identity setting governs deduplication in both surfaces — so a change to that setting between a UI report and an API query produces different counts for the same date range. Recent data can also shift between retrievals while processing continues.
Does server-side tagging remove the need for a separate warehouse pipeline?
No. Server-side tagging moves collection onto infrastructure you control and lets you shape and route data before it leaves, which is a meaningful governance gain. It is still a collection and routing layer, not a storage and modeling layer; the warehouse-side landing zone, validation, and modeled tables described earlier remain necessary.
How long should raw event data be retained?
There is no universal figure. Under Singapore's PDPA, the Retention Limitation Obligation requires an organization to cease retaining personal data, or remove the means of associating it with individuals, once the purpose is no longer served and retention is no longer necessary for legal or business purposes. Set the schedule from your documented purposes and legal requirements, enforce it as policy in the lakehouse, and confirm the specifics with counsel.
What is the minimum viable semantic layer for a mid-size enterprise?
A metric registry with an owner, a written definition, a source-of-truth flag, and a change log; a mapping table between the web tool's event and parameter names and the warehouse's canonical schema; and a written record of the web tool's reporting identity setting as a known divergence. That is enough to make reconciliation meaningful. It does not require a full modeling platform on day one.
Further Reading and Refresh Notes
The primary sources cited in this guide, and what each is useful for:
Google Analytics Data API reporting data expectations — sampling metadata, HLL++ approximation, data thresholding, the
(other)row, reporting identity, freshness, and the vendor's own pointer to BigQuery Export for unsampled event-level analysis.Measurement Protocol (GA4) — the protocol's stated role as an augmentation to gtag, Tag Manager, and Firebase collection rather than a replacement, plus its offline and server-to-server use cases.
Introduction to server-side tagging — how a server container runs on infrastructure you control, how clients transform requests into events, and the recommendation to serve it from a first-party domain in production.
GDPR Article 7 — the requirement to demonstrate consent, the withdrawal right, and the condition that withdrawal be as easy as giving consent.
GDPR Article 17 — erasure grounds and the exceptions that limit them.
PDPC Advisory Guidelines on Key Concepts in the PDPA — the Commission's own text on personal data, consent, notification, retention limitation, and transfer limitation.
Refresh date: 16 November 2026. Two categories change fastest and should be rechecked before the next revision. Vendor capabilities and documentation — reporting identity behavior, sampling limits, export options, and lakehouse feature sets — are revised without notice, so re-read the linked pages rather than relying on this summary. Regulation text and regulatory guidance also change: confirm the current version of any article or guideline before relying on it, and take legal advice on your specific obligations.