Weekly Forecasting with Enterprise Data Agents: The Business Context That Makes a Forecast Actionable
A practical framework for weekly forecasting with enterprise data agents: a seven-part context inventory, forecast vs plan vs target, rolling-origin validation, a failure taxonomy and an acceptance checklist.
Introduction
An enterprise data agent can produce a weekly number on request. It can pull the series, fit a model, and return a forecast with a chart in less time than it takes to open the planning spreadsheet. What it cannot do on its own is know whether that number means what the planning meeting thinks it means.
That gap is the subject of this article. The forecast becomes a decision input only when the business context around it is defined, versioned and validated: which metric, at which grain, on which calendar, under which assumptions, owned by whom, computed from data as it stood at a stated moment. This article supplies five things a data or analytics leader can put to work in a weekly planning ritual:
a seven-part context inventory that specifies what an agent needs before its first forecast;
a separation of forecast, plan and target as three different objects with different owners;
a validation protocol built on rolling-origin backtesting, naive benchmarks, bias checks and prediction intervals;
a failure taxonomy for agent forecasts that go wrong because context was missing, each mode mapped to the inventory element that prevents it;
an acceptance checklist of yes/no gates to run before a forecast drives a decision.
The framing throughout is that forecasting is a problem-definition exercise before it is a modeling exercise. The agent inherits whatever ambiguity the definition leaves in place, and it resolves that ambiguity silently and consistently.
Why a Weekly Forecast Fails Without Business Context
Hyndman and Athanasopoulos describe problem definition as often the most difficult part of forecasting: it requires understanding how the forecasts will be used, who requires them, and how the forecasting function fits within the organization. They also note that a large part of a forecaster's time can go into locating and collating data before any method is developed (Forecasting: Principles and Practice, §1.2 and §1.6).
An agent does not remove that work. It compresses the visible part of it. Ask an agent for "last week's revenue forecast" and it must decide, without asking, what revenue includes, which date field assigns an order to a week, whether returns are netted, which entities are in scope, and which week-numbering convention applies. Each decision is reasonable in isolation. Together they produce a number that is internally consistent, reproducible, and wrong relative to the number finance reports.
The failure is easy to misclassify. It is not model error: the model may have fit the series it was given very well. It is not data-quality error either, in the sense of nulls, duplicates or broken pipelines. It is a definition failure, and it sits upstream of both. This is why the organizing logic of this article runs in the order it does: context first, then the forecast/plan/target distinction, then validation, and only then a taxonomy of what goes wrong when context is absent. Model and data-quality problems are real, but they are the second thing to check, not the first.
The Context Inventory: What an Agent Needs Before Week One
The inventory below is an original organizing framework, built by reasoning about what a weekly forecast consumes; where published material bears on an element, it is cited. The seven elements are:
Metric definitions and calculation boundaries — what the number is, precisely, and which date assigns an event to a week.
Entity relationships and grain — the level at which the forecast is made and how it rolls up.
Calendar and week conventions — fiscal or calendar weeks, week start, holiday calendars, moving holidays.
Planning assumptions — capacity, pricing, promotions, supply and headcount constraints the agent should receive, not infer.
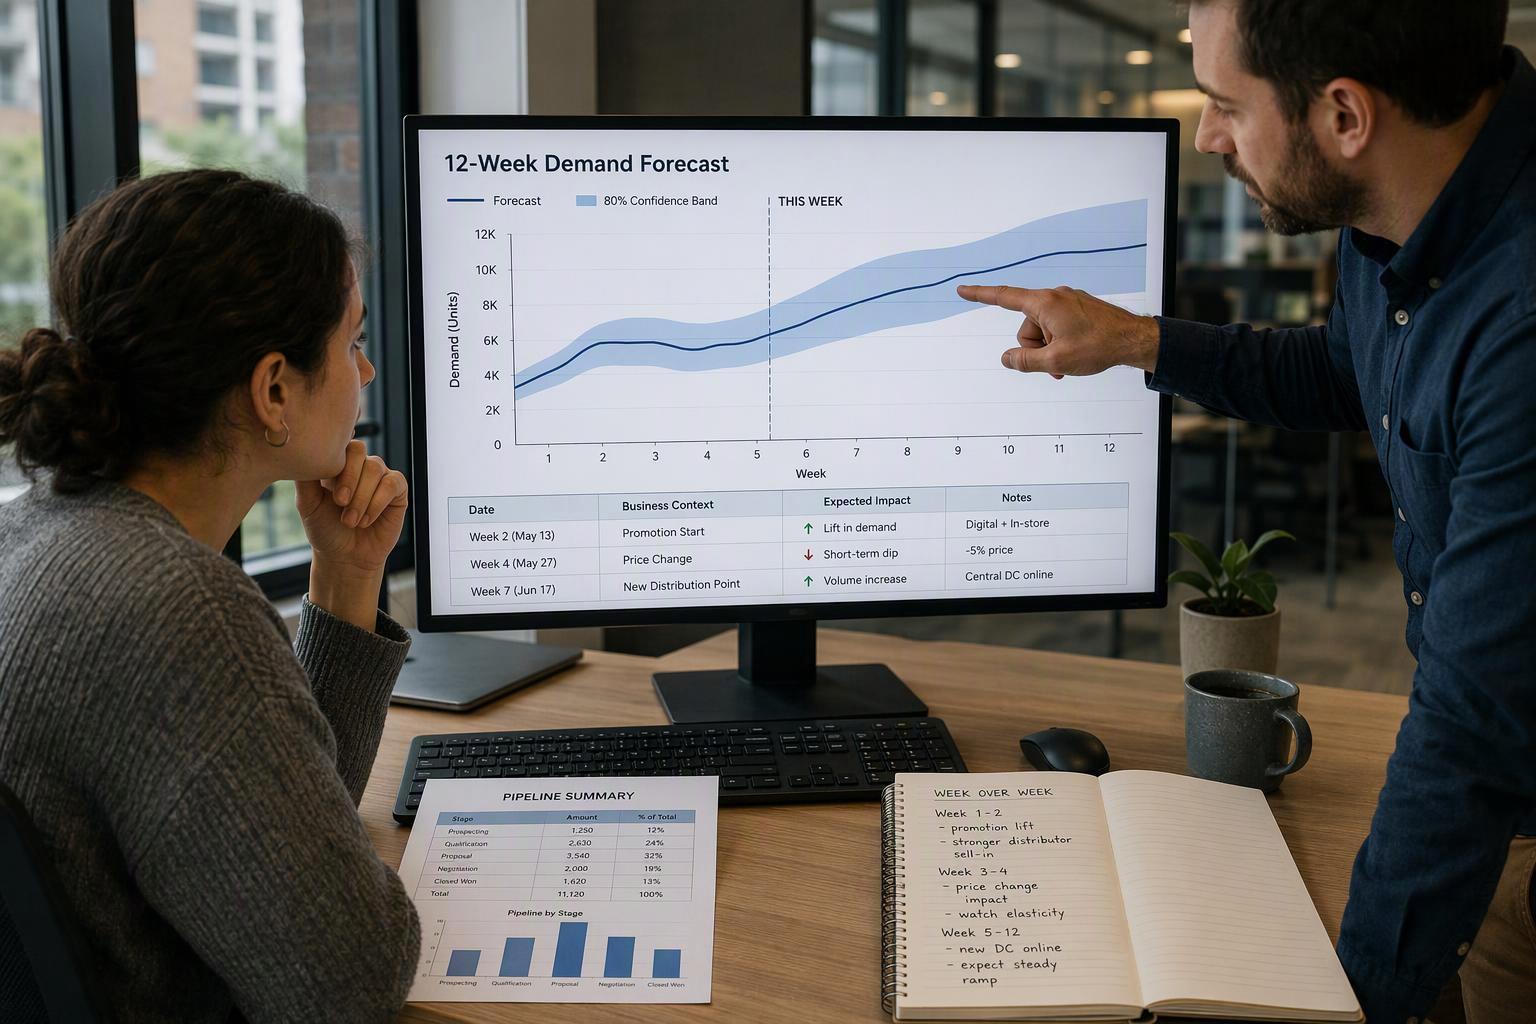
Known events and their expected effect — a register of launches, promotions, closures and contract changes with direction and magnitude.
Ownership and decision rights — who owns the definition, the forecast, overrides and consumption.
Freshness and point-in-time correctness — source latency, revision behavior, and the as-of date of every forecast.
Completeness matters more than sophistication. A partial inventory does not produce a visibly partial forecast; it produces a confident one whose defects surface only when someone tries to reconcile it to the plan.
Metric definitions and calculation boundaries
A weekly metric definition needs, at minimum: numerator, denominator, inclusion and exclusion rules, unit, aggregation level, and the date field that assigns an event to a week. The last item is the one most often left implicit. An order placed on a Sunday evening and fulfilled on Monday belongs to different weeks depending on whether the forecast counts order date or ship date, and the two series will diverge in exactly the weeks where the planning decision is most sensitive.
Two teams can report different numbers under the same metric name without either being wrong. One may include a channel the other excludes; one may net returns at the transaction date, the other at the return date. An agent cannot detect that divergence unless the definition is explicit and enforced. This is the argument for keeping definitions in a semantic layer rather than in query text: the semantic layer is where a definition lives once and is applied everywhere, so that the agent's output and the governed report resolve to the same object.
Entity relationships and grain
A weekly forecast is always at a specific grain — product × region × channel, for example — and the agent must know how entities roll up and which joins are valid. When grain is implicit, the failure is concrete: an agent that joins a shipment table to an order table on order ID without accounting for split shipments will double count revenue for multi-box orders, and the resulting forecast will be too high by a stable, plausible-looking margin. Nothing in the output signals the error. The forecast reconciles to nothing because there is no stated grain to reconcile against.
The practical consequence is that a forecast at the wrong grain cannot be reconciled to the plan it is meant to inform. If the plan is built at region level and the forecast at warehouse level, the roll-up is a modeling decision that someone must own.
Calendar and week conventions
The calendar context an agent needs includes fiscal versus calendar weeks, the week-start day, the 53-week year problem, holiday calendars, and moving holidays such as Easter that shift between periods. These are recognized sources of systematic variation, not noise. Statistics Canada defines calendar effects as including trading-day effects associated with the weekday composition of the month and moving holiday effects associated with non-fixed-date holidays such as Easter (Statistics Canada, 12-539-X). The ONS describes the same mechanisms, noting that trading-day effects arise because months have differing numbers of each day of the week from year to year, and that moving holidays can fall in different months (ONS, Seasonal adjustment).
At weekly frequency the weekday-composition problem largely disappears, since every week has one of each day. What remains is the moving-holiday problem, the week-start convention, and the fiscal-calendar mismatch. The rule that matters: week conventions must be identical across the forecast, the actuals and the plan, or comparisons are invalid. A forecast built on ISO weeks compared against actuals built on Sunday-start weeks will show a persistent error in every week that straddles a month boundary, and that error will look like model error.
Planning assumptions
Between a statistical forecast and a plan sit assumptions the model does not contain: capacity constraints, pricing changes, promotion schedules, supply limits, headcount. These are inputs the agent should receive explicitly rather than infer from history. An unstated assumption becomes an invisible constraint on the forecast's usefulness — the forecast may be a good prediction of demand and still be useless for planning, because the planner knows the warehouse cannot ship more than a fixed volume next week and the forecast does not say whether it exceeds that volume.
Known events and their expected effect
An event register covers launches, promotions, closures, contract changes and one-off campaigns. The distinction that matters is between an event with a documented expected direction and magnitude and a vague annotation. "Big promo week" tells the agent nothing it can use; "20% price cut on SKU family A, weeks 14–15, expected volume uplift 30–40% based on the prior two promotions" gives it a timing, an affected entity set and an expected effect. Without that, the agent will treat a planned spike as organic demand and extrapolate it into the baseline.
Ownership and decision rights
Four roles need to be assigned: who owns the metric definition, who owns the forecast, who approves overrides, and who consumes the output. Hyndman and Athanasopoulos are direct on the design principle: forecast accuracy may be impeded if the forecasting task is carried out by users of the forecasts, and forecasters and users should be clearly segregated, with the forecaster sometimes delivering a reality check to the user (§6.2). They also document the risk on the other side: practitioners adjust statistical forecasts much more often than they should, and often for the wrong reasons, with adjustment creating a feeling of ownership rather than improving accuracy.
Ownership is therefore a design decision with accuracy consequences, not an administrative detail.
Freshness and point-in-time correctness
The agent must know which sources arrive when, which are restated, and what as-of date a forecast was produced from. Singdata's published material on data freshness argues that freshness requirements should be set by the decision rather than by the label: many scenarios described as real-time do not require second-level latency from a business perspective, and a dashboard refreshing every 1 to 15 minutes may not degrade decision quality relative to one refreshing every 5 seconds (Singdata, Data Freshness and Dynamic Tables). For a weekly forecast, that reasoning cuts toward minute-level or hourly freshness being sufficient for most inputs — but the weekly cadence still imposes a hard deadline, which makes freshness a constraint rather than a preference.
Point-in-time correctness is the sharper requirement. A backtest that uses restated data overstates accuracy, because the model is being scored on information it would not have had at the forecast origin. The as-of date must be recorded with every forecast, and the backtest must replay data as it stood at each origin.
Forecast, Plan and Target Are Three Different Objects
A forecast is a prediction of what will happen. A plan is a committed course of action. A target is a desired outcome. The three have different owners, different validation standards and different failure modes, and conflating them corrupts both the forecast and the plan.
Hyndman and Athanasopoulos note that goals are too often set without any plan for how to achieve them, and without forecasts for whether they are realistic (§1.2). They also describe the forecaster's role in the new-product case as delivering a reality check to the user, where the forecast of sales volume may differ considerably from what management hopes sales will be in order to meet financial objectives (§6.2).
That reality check only works if the forecast is allowed to disagree with the target. A forecast bent toward a target loses its diagnostic value: it can no longer tell you that the target is unreachable, because it has been adjusted until it agrees. A plan built on an optimistic forecast fails operationally: capacity, inventory and staffing are committed against a number that was never a prediction. Keeping the three objects separate is what allows the organization to see the gap between them and decide what to do about it.
Why a Statistically Good Forecast Is Not Automatically a Good Decision Input
Accuracy metrics are necessary and not sufficient. Hewamalage, Ackermann and Bergmeir make the case directly: forecasting and the respective accuracies of models alone are not sufficient, but rather how the produced forecasts affect the downstream decision-making processes, and the final accuracy of evaluated models needs to be closely tied to business utility as seen by the downstream processes being optimized (Forecast Evaluation for Data Scientists). They cite evidence from the M5 competition dataset that simpler empirical methods may outperform sophisticated ML models when the focus is on downstream inventory optimization, and conclude that the relationship between accuracy and final business utility is often not linear — a fine-grained improvement of one model over another does not necessarily guarantee significantly improved business value.
The second reason a statistically good forecast can be a bad decision input is cost asymmetry. Over- and under-forecasting rarely cost the same. A staffing forecast that under-predicts by 10% produces service failures and overtime; one that over-predicts by 10% produces idle capacity. A forecast that minimizes average error treats those two outcomes as equivalent, and if the decision does not, the forecast is optimizing the wrong objective. Hewamalage et al. make the related point that error measures can be asymmetric by construction — sMAPE, for instance, penalizes underestimates more than overestimates for the same actual value, an asymmetry that may be of interest in domains where underestimates are considered more costly.
This is where the agent's business context must enter the forecast: cost structure, service levels and capacity belong in the objective, not in a footnote to the accuracy report.
Validating a Weekly Forecast Before It Drives a Decision
The protocol below is a sequence. Each step answers a question the next step assumes. No universal accuracy threshold is offered here, deliberately: a threshold has to be derived from the decision's tolerance for error and its cost asymmetry, and inventing a number would substitute a false standard for that derivation.
Backtesting with rolling origin
In a fixed-origin evaluation, the forecast origin and training region are fixed and forecasts are computed for each step of the horizon. In a rolling-origin evaluation, the horizon size is fixed but the origin advances through the series, creating multiple test periods, with new data available for refitting at each origin (Hewamalage et al., §2; Svetunkov, ADAM §2.4).
Svetunkov states the problem with the fixed-origin approach plainly: using it only once can give a misleading impression of accuracy, because if the series contains outliers or level shifts, a poor model might perform better in fixed-origin evaluation than a more appropriate one just by chance. Hewamalage et al. add that for many practical scenarios a fixed-origin setup is problematic and may not be a sufficient evaluation, since for a single series it provides only one forecast per horizon step and the testing period is short.
In practice, the rolling-origin setup for a weekly forecast is: fix the horizon (one week, or four weeks if the plan looks further out), advance the origin week by week, refit or update as new data arrives, and score every origin. The data-leakage risk Hewamalage et al. emphasize connects directly to point-in-time correctness: if the backtest reads restated data rather than the vintage available at each origin, the accuracy estimate is inflated and the inflation is invisible in the output.
Benchmark against a naive forecast
Any model, agent-assisted or not, should be compared to a simple benchmark. The SAS forecast value added (FVA) white paper defines FVA as the change in a forecasting performance metric attributable to each step and participant in the forecasting process, and describes the standard naive models as the random walk (Naive Forecast 1) and the seasonal random walk (Naive Forecast 2), with NF2 often preferred for seasonal data (SAS, Forecast Value Added Analysis). Hewamalage et al. make the same point from the evaluation side: on series with clear seasonal patterns, models should be benchmarked against the seasonal naive model as the most simplistic benchmark.
The framing here is methodological, not a product claim. The question FVA answers is whether the added complexity — including the agent itself — earns its keep. The SAS paper's blunt formulation is worth keeping: if you don't know that you are beating a naive forecast, then maybe you're not.
Bias and error-direction checks
Mean error and error direction matter separately from magnitude. Hyndman and Athanasopoulos note that if the residuals have a nonzero mean, the forecasts are biased, and that adjusting for bias is easy: if the residuals have mean m, add m to all forecasts (§5.4).
The decision consequence is the asymmetry from the previous section. A forecast with acceptable MAPE but persistent under-forecasting is a bad input for a service-level decision, because the average error hides a directional error that the decision is sensitive to. Bias should be reported alongside magnitude, and reported by direction, not netted away.
Prediction intervals and uncertainty communication
Prediction intervals usually increase in length as the forecast horizon increases: the further ahead the forecast, the more uncertainty, and thus the wider the interval (Hyndman and Athanasopoulos, §5.5). A weekly forecast delivered as a point estimate hides the information a planner needs — whether the number is tight enough to commit capacity against, or so wide that the decision should wait.
The interval should be presented alongside the point forecast, with the coverage level stated. When the interval is too wide to support the decision, the agent's correct behavior is to escalate rather than guess: flag the width, name the driver if it can, and route the decision to the owner.
Exception handling and override discipline
When the forecast is implausible, someone will want to change it. The evidence on judgmental adjustment is not encouraging. Hyndman and Athanasopoulos write that practitioners adjust much more often than they should and many times for the wrong reasons, and that judgmental adjustments should not aim to correct for a systematic pattern in the data thought to have been missed by the model, since this has proven ineffective — forecasters tend to read non-existent patterns in noisy series (§6.2). The SAS FVA paper reports a related finding from one company: small adjustments had essentially no impact on forecast accuracy, while large adjustments, particularly downward ones, tended to be beneficial.
Overrides should therefore be a governed process, not a correction of the model's blind spots: an owner, a stated rationale, a log entry, and an FVA evaluation of whether the override added value. An override that cannot be evaluated cannot be defended or reversed.
Where Agents Fail Because Context Is Missing
The taxonomy below is reasoned from the context inventory. These are testable failure modes, not observed frequencies; no claim is made about how often each occurs. They are distinct from model failures and data-quality failures, and each maps to a missing inventory element so the cause can be traced.
Definition drift and silent metric substitution
The agent resolves an ambiguous metric name to a plausible but different definition, producing a forecast that is internally consistent and externally wrong. Maps to: metric definitions. Test: does the agent's output reconcile to the governed definition, line by line, for a sample of weeks?
Grain collapse and double counting
The agent aggregates across incompatible entity relationships, double counting or losing rows. Maps to: entity relationships and grain. Test: does the forecast reconcile to the source at the stated grain, and does the sum of the parts equal the whole?
Calendar misalignment
The agent uses a different week convention or ignores a moving holiday, producing a systematic error that looks like model error. Maps to: calendar and week conventions. Test: does the forecast's week definition match the actuals and the plan, including the treatment of the holiday weeks?
Treating planned events as organic demand
The agent extrapolates a promotion or launch into the baseline. Maps to: known events. Test: are documented events excluded from or explicitly modeled in the baseline, and does the forecast for the event week differ from the surrounding weeks in the direction the register states?
Stale or restated inputs
The agent forecasts from data that has since been revised, or from a source whose latency it did not account for. Maps to: freshness and point-in-time correctness. Test: can the forecast be reproduced from the data as it stood at the forecast date?
Unowned overrides
An override is applied without a recorded owner or rationale, so it cannot be evaluated or reversed. Maps to: ownership and decision rights. Test: is every override attributable and measurable, and does its FVA record show whether it helped?
How the Weekly Cadence Changes the Problem
A one-week horizon is short but not easy. The signal-to-noise ratio is low, week-to-week variation is dominated by calendar and event effects, and the forecast is consumed by a recurring planning ritual with fixed timing. The ECB's account of short-term forecasting with high-frequency indicators is instructive on the general problem: short-term forecasts typically rely on data available at monthly, weekly or daily frequency with shorter publication delays, and the tools must combine information from data collected at different frequencies and deal with the "ragged edge" caused by different publication delays (ECB Economic Bulletin, 2020). The same article notes that changes in economic relationships are a challenge to forecasting models in general and to short-term forecasting tools in particular.
Short horizon, noisy signal
A short-horizon forecast can be accurate in absolute terms and still uninformative about week-to-week change. If last week's value is a good predictor of this week's, a naive forecast will score well and tell the planner nothing about whether this week differs. The evaluation should therefore be against the decision the forecast supports, not against a generic accuracy target: the question is whether the forecast distinguishes the weeks where the decision changes, not whether its average error is small.
Seasonality and calendar effects at weekly frequency
Weekly seasonality and calendar effects require enough history to estimate. Statistics Canada's guidance recommends a span of 10 to 15 years of data for proper identification and estimation of seasonal and calendar effects, with a minimum of five years to properly estimate a seasonal pattern and seven years for calendar effects such as trading days and moving holidays (12-539-X). That guidance is written for monthly and quarterly series under a seasonal-adjustment program, and should not be transplanted to weekly data as a rule. The transferable point is narrower: the agent needs enough history for the effects it claims to model, and should not claim an effect it lacks history to estimate.
The planning ritual as a constraint
The weekly meeting's timing, attendees and decision rights shape what the forecast must deliver: a number by a deadline, with an interval and an explanation. The deadline makes freshness a hard constraint — a perfect forecast that arrives after the meeting is not a forecast, it is a post-mortem. The attendees determine who can approve an override, which connects back to ownership. And the decision rights determine what the forecast is for: a capacity commitment, a purchasing signal, or a variance explanation against plan.
An Acceptance Checklist Before the Forecast Drives a Decision
The checklist below is an original synthesis of the framework in this article. It is not a certification or an industry standard. Each gate is a yes/no question with the test the reader runs.
Definitions reconciled. Does the forecast's metric reconcile to the governed definition for a sample of past weeks, including inclusion and exclusion rules and the date field that assigns events to weeks?
Grain and entity relationships verified. Does the forecast reconcile to the source at the stated grain, and does the sum of the parts equal the whole?
Week convention and calendar effects confirmed. Is the week definition identical across the forecast, the actuals and the plan, and are moving holidays handled explicitly?
Known events registered and modeled. Are documented events excluded from or explicitly modeled in the baseline, with timing, affected entities and expected effect?
Freshness and as-of date recorded. Does the forecast carry the as-of date of its inputs, and is each source's latency documented?
Rolling-origin backtest completed against a naive benchmark. Has the forecast been scored across multiple origins, and does it beat the naive or seasonal-naive benchmark by a margin that matters for the decision?
Bias direction checked. Is mean error reported by direction, not just magnitude, and is any persistent bias corrected or explained?
Prediction interval presented. Is the interval shown alongside the point forecast with its coverage stated, and is the decision still supportable at that width?
Overrides owned and logged. Is every override attributable to a named owner with a rationale, and is its FVA measured?
Decision-cost asymmetry stated. Has someone written down what over- and under-forecasting cost, so the forecast's objective matches the decision's?
Evaluating a Platform for Agent-Assisted Weekly Forecasting
The criteria below are neutral questions the reader can test, not a product rating. They draw on Singdata's first-party description of its AI lakehouse and enterprise data agents, which describes analysis domains, semantic context and permission boundaries enabling an Analytics Agent to turn business questions into verifiable SQL, tables and charts, and describes built-in safeguards that protect write and high-risk actions in its agent tooling (singdata.com). The questions are the same ones a reader should ask of any platform.
Does the platform expose and enforce metric definitions? A semantic layer that holds definitions once and applies them everywhere is the mechanism that prevents definition drift. Ask to see a definition changed in one place and reflected in both the governed report and the agent's output.
Does it preserve point-in-time data for backtesting? Without historical vintages, a rolling-origin backtest reads restated data and overstates accuracy. Ask how the platform stores and replays data as it stood at a past date.
Does it record the as-of date and source latency? Every forecast should carry the moment its inputs were read. Ask where that metadata lives and whether it is queryable.
Does it log agent actions and overrides with attribution? Governed overrides require an owner, a rationale and an evaluation. Ask to see the log and the FVA report built from it.
Does it let you run your own backtest rather than accept a vendor benchmark? Any performance figure a vendor publishes — including Singdata's — is vendor-reported and should be validated in your own environment, on your own series, against your own naive benchmark.
These questions do not require a particular architecture. They require that the platform make the context visible, versioned and testable, which is the same requirement the context inventory places on the forecast itself.
Conclusion
A weekly forecast is only as actionable as the business context behind it, and that context is a defined, owned, versioned asset — not a tacit understanding held by the analyst who built the spreadsheet. An agent makes the context gap more visible, not less: it will produce a number every week, and the number will be wrong in exactly the ways the context left undefined.
The immediate next action is the acceptance checklist. Run it against last week's forecast before the next planning cycle. Where a gate fails, the failure points to a specific inventory element, and that element is the work to do before the next weekly cycle: write the metric definition down, state the grain, fix the week convention, register the events, record the as-of date, assign the owners.
The larger point is that this work compounds. A context inventory that is complete, owned and versioned turns the weekly forecast from a recurring argument about whose number is right into a decision input the organization can act on — and it is the same asset that makes any agent-assisted process auditable, whether the agent is forecasting demand, explaining a variance, or answering a business question in natural language.
Frequently Asked Questions
What is the difference between a forecast and a plan?
A forecast predicts what will happen; a plan commits to what the organization will do; a target states what is desired. Mixing them degrades both: a forecast bent toward a target loses its diagnostic value, and a plan built on an optimistic forecast fails operationally. See the section on forecast, plan and target above.
How much history does an agent need for a weekly forecast?
It depends on the effects being modeled — trend, weekly seasonality, annual seasonality, calendar effects — and the agent should not claim an effect it lacks history to estimate. Statistics Canada recommends 10 to 15 years for proper identification and estimation of seasonal and calendar effects, with a minimum of five years for a seasonal pattern and seven years for calendar effects, but that guidance is written for monthly and quarterly series under a seasonal-adjustment program and should not be transplanted to weekly data as a rule (12-539-X).
Can an agent override a statistical forecast?
Overrides should be governed: owned, evidenced, logged and evaluated for value added. Hyndman and Athanasopoulos caution that practitioners adjust much more often than they should and often for the wrong reasons, and that adjustments should not aim to correct a systematic pattern the model is thought to have missed (§6.2). The SAS FVA method provides the evaluation logic: measure the change in the performance metric attributable to the override (SAS). No specific override rate is acceptable in general.
How do we know the forecast is good enough to act on?
"Good enough" is defined by the decision's tolerance for error and its cost asymmetry, not by a universal accuracy target. The evidence base is rolling-origin backtesting, comparison against a naive benchmark, bias checks by direction, and the width of the prediction interval relative to what the decision can absorb.
What should we check first if the agent's forecast looks wrong?
Work through the failure taxonomy in order before assuming a model problem: definition, grain, calendar, events, freshness, ownership. Each maps to an inventory element, and each has a test that either passes or points to the fix.