
What Makes Data AI-Ready?
AI-ready data is data that is defined, documented, and computable. Learn the three testable conditions that decide whether your AI returns an answer — or the right one.
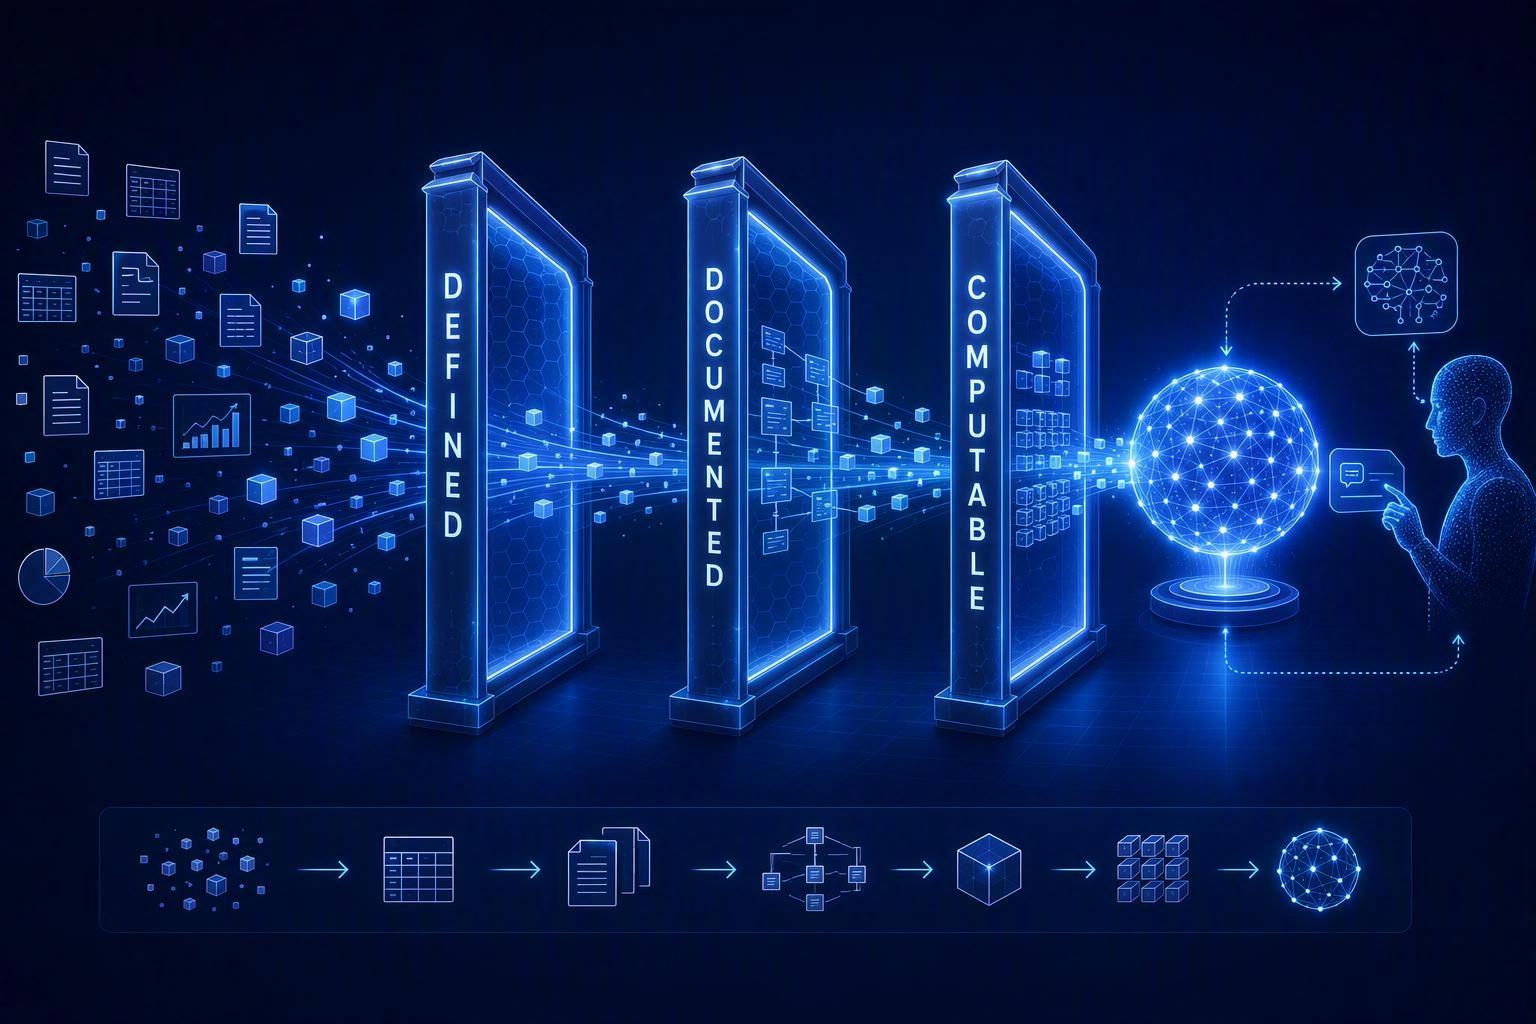
AI-ready data is defined, documented, and computable. That three-part claim is easy to write and deceptively hard to achieve, because each word names a failure your organization has probably already hit.
The chips in AI models and the engines behind them keep getting better. Every few months a benchmark shows another leap in raw number-crunching. Yet most enterprise AI projects still fail, and the reason is rarely the model. It is the data sitting underneath the model — data that was never built to be read, understood, and queried by a machine with no human nearby to explain what it means.
Call that data "AI-ready" and you are really making three separate promises about why it is safe to hand to a model or, increasingly, to an autonomous data agent that will query it around the clock. Each promise is testable. Each one, when broken, produces a specific, familiar failure. This is why "AI-ready data" is not a marketing phrase — it is a diagnostic you can run against any table you plan to expose to AI.
Why the Bottleneck Isn't the Model
Before defining the three criteria, it is worth being precise about the failure they prevent. Natural-language analytics and AI agents do not fail because models are bad at writing SQL. They fail because the model has to guess at things that were never written down: which table is canonical, how two tables join, what "revenue" actually counts.
The cost of guessing is measurable. According to Gartner's own research, organizations will abandon about 60% of AI projects not supported by AI-ready data through 2026, with poor data quality repeatedly cited as a leading cause of the rest. Teams do not run out of model capability or compute; they run out of data that is trustworthy enough to run on.
The numbers bear this out. Frontier models score impressively on clean academic schemas, then collapse on real enterprise warehouses. On the Spider 2.0 benchmark — built from real, ~800-column enterprise schemas — even the best systems answered only around 10–21% of questions correctly, a stark contrast to the 86%+ they reach on the academic Spider 1.0. In dbt Labs' 2026 benchmark, raw text-to-SQL on modeled enterprise data landed between 84% and 90% accuracy; the same setup reached 98–100% once the meaning of the data was made explicit and machine-readable.
Here is the uncomfortable part: the failure is usually silent. The SQL executes, the dashboard fills, and the number is simply wrong — because the model picked the wrong metric, the wrong join, or the wrong interpretation of an ambiguous question. Analysts describe this escalation of wrong-but-plausible answers as metric drift, where two people asking the "same" question get different numbers and then argue about who is right.
That is not a model problem. It is a data problem, and it has exactly three roots. Data is AI-ready only when it is defined, documented, and computable.
Defined: One Governed Meaning
The first bar is semantic. Data is only useful to an AI if it means one thing at a time — and means it consistently across the people, tools, and agents that consume it.
"Revenue," "active customer," and "churn" are the classic examples. They are not column lookups; they are decisions about filters, time logic, exclusions, and aggregation. In one system, revenue might be recognized; in another it is billed; in a third it is collected. When a model is pointed at a raw schema, all three look like "revenue," and it has no way to choose. As Atlan's analysis of enterprise text-to-SQL puts it, metric drift happens because the same question returns different answers across tools unless the underlying definition is shared.
Defining data means more than giving a column a friendly name. It means a governed, owned definition of each business metric — the calculation, the inclusion and exclusion rules, the grain, the time logic — plus the synonyms people actually use. What finance calls bookings, sales may call new ARR; an AI needs to know they are the same thing. This is exactly what a governed semantic layer encodes for AI data teams, and it is why grounding queries in one consistently can move accuracy from the mid-80s to near-perfect.
A useful test: can you point to where a core metric like revenue is defined, who owns that definition, and what synonyms resolve to it? If the answer is scattered across slide decks and a veteran analyst's memory, your data is not defined — and no model upgrade will fix it.
Documented: Machine-Readable Context and Lineage
The second bar is about discoverability. Even perfectly defined data is useless to an AI if the definition and provenance are not something a machine can actually read.
This is a specific, and widely missed, distinction. Human documentation — a wiki page, an ad hoc README — describes data for people to browse. An AI agent does not read that. It needs structured, queryable metadata: field-level definitions, units, grain, permitted values, owner, sensitivity, and deprecation status, attached to the data itself. Collibra's work on metadata as the AI context layer makes the point directly: without this context, an agent cannot tell which of several competing definitions of a metric is authoritative, or which pipeline produced it.
Lineage is the other half of documentation. Data lineage records where each value came from, how it was transformed, and when it was refreshed. It is what makes an AI answer auditable and reproducible — you can walk the path from the number on the screen back to its source, and explain why you trust it. And when an answer is wrong, lineage is what lets you find the upstream source, transformation, or stale snapshot that caused it, instead of guessing.
Treat documented data as active infrastructure, not paperwork. If metadata and lineage are an afterthought, an agent is effectively operating blind — confidently, but blind.
Computable: Governed and Actually Queryable
The third bar is about reach and safety. Data can be perfectly defined and perfectly documented and still not be AI-ready if the machine that needs it cannot compute on it safely and legally.
Computable has two parts, and both matter. The first is technical: the data must actually live somewhere an AI can query it, in a form that is structured, current, and linkable — not trapped in an unreadable export or a format no engine consumes. The second is governed access: exposing data to autonomous agents and large language models changes the risk profile. Immuta's guidance on how AI agents are reshaping data governance is blunt: agents are no longer human analysts who happen to be faster. They are non-human identities that need distinct credentials, least-privilege scopes, masking for sensitive fields, and immutable audit trails.
An enterprise exposing petabyte-scale customer data to an agent is, in practice, an exercise in access control, row- and column-level security, PII masking and redaction, and compliance evidence across GDPR, CCPA, and SOC 2. If the data is simply not safe or not legal to expose to compute, then regardless of how well it is defined and documented, it is not AI-ready. It is also not current — an agent making a decision on a stale batch snapshot is making a decision on data that no longer reflects reality.
How the Three Hold Together
Defined, documented, and computable are not three independent checklists; they are a sequence with a logic to it. You define meaning, you document it so machines can find and trust it, and only then do you let compute — models, agents, natural-language analytics — act on it safely. Skip any stage and the downstream one becomes guesswork.
This framing is deliberately narrower than the many lists you will find elsewhere. Snowflake's popular AI-ready data framework organizes readiness into six Cs — clean, contextual, consumable, current, correlated, compliant — and FAIR principles (findable, accessible, interoperable, reusable) describe machine-actionability from a research angle. Those are useful lenses. But the three conditions we are arguing for are the ones you can actually test and act on at the platform level, and they are the ones that map directly to how AI agents fail: when meaning is ambiguous (not defined), when context is undiscoverable (not documented), and when data cannot be reached safely (not computable).
Isn't This Just Data Quality?
The fairest challenge is that "defined, documented, and computable" sounds like data quality wearing new clothes. It is worth answering directly.
Traditional data quality cares about whether the values in the fields are correct, complete, consistent, and timely — is the number right? AI-readiness extends beyond that to whether the data can be interpreted and acted on by a machine with no human present. A dataset can be clean and complete and still be useless to an AI because its columns mean different things to different teams, it has no discoverable lineage, or nobody governing what an agent may touch. Data quality asks if the answer is accurate. Data readiness asks if the system can arrive at the right, allowed, and explained answer in the first place.
Likewise, "can't we just use a smarter model?" misses the mechanism of the failure. Give a better model the same ambiguous schema and it will produce the same confidently wrong answer faster. The remedy is not more model capability; it is giving whatever model you use meaning it can rely on, context it can read, and data it is permitted and able to compute on.
How to Assess Your Own Data
You do not need a large migration project to find out whether your data is AI-ready. Start with a single metric your business actually argues about, and run it through the three tests. Each should be answerable today, by a named owner, not by a search through tribal knowledge.
Defined: Where is this metric defined, and who owns the definition? Can you state its calculation, grain, filters, and time logic? Can you list the synonyms that resolve to it? If finance and operations would define "revenue" differently, you are not there yet.
Documented: Is that definition discoverable by a machine — attached as structured metadata with lineage showing where the value came from and how it changed? Could an agent or analyst trace the number back to source and reproduce it? If the meaning lives in someone's head or a slide deck, you are not there yet.
Computable: Is the underlying data in a place an AI can actually query, current enough for the decision you are making, and safe — with access control, masking, and audit — to expose to autonomous agents and a model context window under your compliance obligations? If touching it requires a human intervention or clears compliance by being unqueryable, you are not there yet.
The honest result for most enterprises is a "no" on one or more conditions for most of their data. That is not failure; it is an inventory. The point of the bar is to stop pretending that a better model, a bigger engine, or a demo that works on one polished table will close the gap.
When those three conditions are met, the pattern becomes practical at enterprise scale. A governed layer in which metrics are defined once and surfaced with lineage is the mechanism behind an AI-native lakehouse that keeps AI close to the data it runs on — and it is what lets an Analytics Agent map a plain-language question to the right governed metric and return an answer you can verify. Defined data is what makes that possible; documented and computable data is what makes it trustworthy enough to act on.
Stop measuring AI-readiness by the sophistication of your model. Measure it by whether the data underneath is defined, documented, and computable — because those are the conditions that determine whether your AI returns an answer, or returns the right one.
If you are starting to assess your data foundation against these three conditions, Singdata builds and operates governed, AI-native platforms around exactly this bar — start with a single metric your teams argue about and see how far the three tests take you.