Best Text-to-SQL and Natural Language BI Tools for Enterprise Data Teams in 2026
A 2026 comparison of text-to-SQL and natural language BI tools — Snowflake Cortex Analyst, Databricks Genie Agents, ThoughtSpot Spotter, Omni, Looker, Power BI Copilot, Hex, Wren AI and Vanna — judged on SQL inspectability, permission enforcement, semantic modeling burden, metric inheritance, open-source cost and stack fit, with a pilot acceptance checklist.
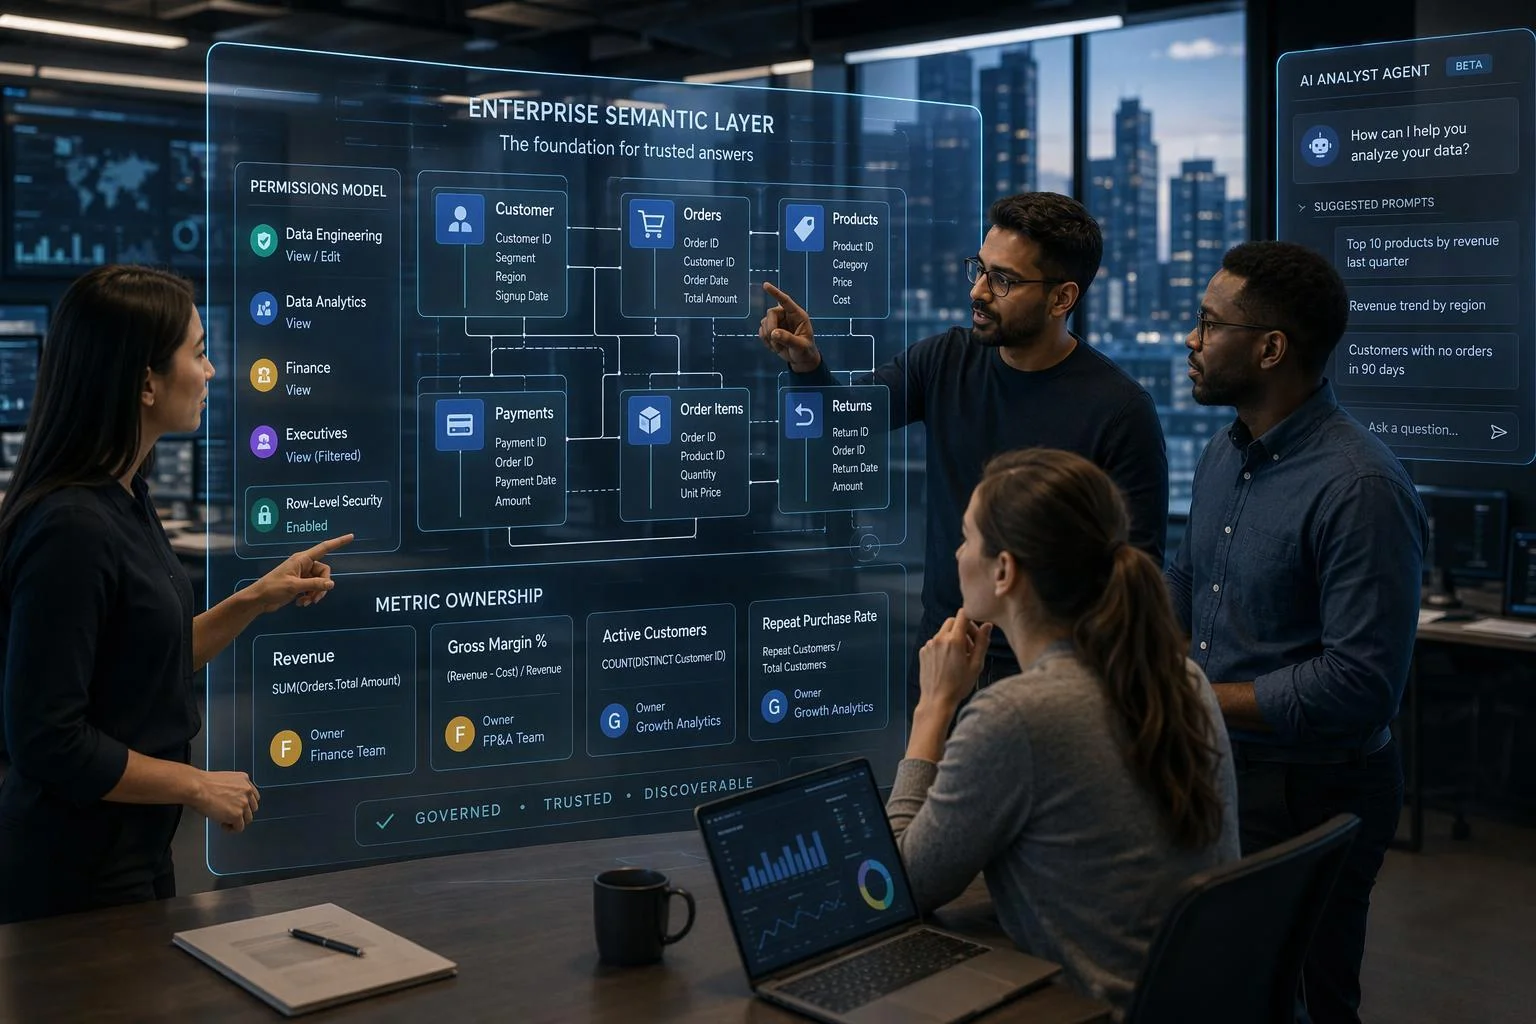
The agent is rarely the weak link. In most enterprise text-to-SQL deployments that disappoint, the failure traces back to the team rather than the model: a semantic layer that never got written down, a permissions model that was never tested as a governed user, and a metric that three groups define three ways. A well-aligned agent on a poorly aligned team produces confident wrong answers faster than the old dashboard ever did.
This guide covers the tools enterprise data teams are evaluating in 2026 — warehouse-native assistants, BI-native conversational layers, code-notebook agents, and open-source frameworks — against six criteria drawn from the questions buyers actually ask: can you see the SQL, how are permissions enforced, how much modeling must you build first, does the tool respect your metric definitions, what does open source really cost you, and does it fit your stack. The comparison matrix comes first so you can orient quickly; the reasoning follows; the acceptance checklist at the end is the artifact to take into a pilot.
There is no single winner. The shortlist splits by stack and by how much semantic modeling your team is prepared to own.
Comparison Matrix: Text-to-SQL and NL BI Tools at a Glance
Tool | Category | Where the semantic model lives | Generated SQL inspectable | Permission enforcement | Stack fit | Main trade-off |
|---|---|---|---|---|---|---|
Snowflake Cortex Analyst | Warehouse-native | Semantic view (YAML with dimensions and facts) staged in Snowflake | Yes — responses return the interpreted question and the SQL statement | Snowflake RBAC and privilege management; semantic view access controlled by the stage | Snowflake, in supported regions | Native governance, but region-limited and requires a maintained semantic view |
Databricks Genie Agents | Warehouse-native | Agent-scoped knowledge store (table and column descriptions, synonyms, joins, SQL expressions) | Yes — Chat mode returns single-query answers; Agent mode returns reports with citations and supporting tables | Inherits permissions from the enclosing workspace folder; data access evaluated against each end user's Unity Catalog permissions | Databricks | Mode trade-offs: Chat mode cannot break a question into steps |
ThoughtSpot Spotter | BI-native | Relational search model | Answers are grounded in the model; Spotter is built on the search model for interpretable results | BI model governance | Multi-source via the BI layer | Requires data-model readiness and ongoing coaching |
Omni | BI-native | Omni semantic model (YAML) | AI-generated queries use the same governed definitions as the rest of the platform | Every AI query respects row-level security and user-level access controls | Multi-warehouse via the semantic model | Modeling is the prerequisite; AI quality tracks model quality |
Looker Conversational Analytics | BI-native | Looker semantic model (LookML) | Grounded in the Looker model | Carried by the Looker model; agents require | BigQuery, AlloyDB, Redshift, Snowflake, Databricks | Explore conversations are limited to one Explore and are not shareable |
Power BI Copilot | BI-native | Power BI semantic model (DAX) | Generates DAX; Microsoft advises reviewing generated DAX before applying it | Tenant-level admin toggle; operates inside the tenant | Power BI / Fabric capacity in a supported region | Requires paid Fabric capacity (F2+) or Premium (P1+); not supported in sovereign clouds |
Hex | Code-notebook | Hex semantic models, plus workspace context | Notebook Agent is positioned for technical users who can audit the SQL and code | Workspace roles and project permissions | Warehouse-connected notebooks | Best value for code-first teams; not a no-model self-service layer |
Wren AI (OSS) | Open-source framework | MDL (Modeling Definition Language) | Service performs retrieval, prompting, SQL generation, and validation | Listed as part of the collaboration layer; deployer configures | Multi-engine via the context layer | You own deployment, upgrades, and governance |
Vanna | Open-source framework | Training context you supply | Generation and validation stages are exposed by design | Deployment-configuration question per the vendor's security FAQ | Deployment-agnostic | A framework, not a product; you build the application |
Read the "semantic model location" column first. It predicts maintenance burden more reliably than any accuracy claim on a vendor page: a model that lives inside the warehouse is maintained by the data engineering team that already owns the warehouse, while a model that lives in a separate BI tool is a second surface someone must keep current.
The accuracy figures that circulate for these tools need the same scoping. On Spider 2.0, a benchmark of 632 real enterprise workflows with schemas averaging roughly 800 columns, the best reported result was 21.3% — against 91.2% on Spider 1.0's smaller, cleaner academic schemas. A curated semantic model moves the number far more than a model upgrade does: dbt Labs reported 100% on an 11-question insurance set with a semantic layer in front of the model, versus 84.1% raw. Treat every vendor accuracy figure as a claim about that vendor's own curated context, not about your schema.
Evaluation Criteria: How We Compared These Tools
Six criteria drive the sections that follow, and each one corresponds to a question you can answer with evidence from a pilot rather than a demo.
SQL inspectability. Can a reviewer see the query the agent produced, and can it be executed and checked against a known answer? A tool that hides the query behind a proprietary layer makes every other test in this article impossible to run.
Permission enforcement model. Is row- and column-level access enforced natively by the platform, inherited from a governance layer that already exists, or left to the deploying team? The distinction matters more than the feature list, because it determines who is accountable when a governed user asks a question they should not be able to answer.
Semantic modeling burden. What must the team build before the first trustworthy answer — a YAML semantic view, a search model, a LookML project, an MDL file, or a training set? This is the criterion that most often decides whether a pilot succeeds, because it is a staffing question disguised as a technical one.
Metric-definition inheritance and conflict handling. When two teams define "active customer" differently, does the tool return the governed definition, silently pick one, or surface the ambiguity? Only the third behavior is safe at enterprise scale, and only the first is efficient.
Open-source versus commercial trade-offs. License price is not total cost of ownership. The real comparison is who maintains the model, the evaluation harness, the permission layer, and the upgrade path in month twelve.
Warehouse and lakehouse fit. Does the tool run natively against your engine, or does it require a copy of the data somewhere else? Dialect divergence means the same question compiles differently across Snowflake, Databricks, and BigQuery, so single-engine benchmarks understate portability cost.
Accuracy benchmarks alone are a poor selection criterion, and the published spread shows why. In the Spider 2.0 paper, the same o1-preview code-agent framework scores 91.2% on Spider 1.0, 73.0% on BIRD, and 21.3% on Spider 2.0 — whose 632 real enterprise workflows have schemas averaging roughly 800 columns. The model did not change between those rows. The schema did. A benchmark number measured on small, clean, cross-domain schemas tells you very little about a production warehouse with duplicated column names and undocumented join paths.
There is a second measurement problem. Benchmarks typically run as a superuser, which means they measure a query no governed production user could ever execute. A system that scores well under those conditions has not demonstrated that it enforces row-level security correctly, only that it can write SQL when nothing stands in its way.
SQL Inspectability: Can You See and Audit the Query?
Inspectability is an architectural property, not a feature checkbox, and it splits the market cleanly.
Warehouse-native tools generate SQL against the warehouse and return it. Snowflake's Cortex Analyst response format includes both the interpreted question and a sql statement, so a reviewer sees exactly what ran. Databricks Genie Agents expose SQL across their modes, but the modes differ in what you get back: Chat mode answers structured-data questions with a single SQL query, while standard Agent mode breaks a complex question into sub-tasks, runs multiple queries, and returns a report with citations, visualizations, and supporting tables. If your reviewers need to trace a multi-step answer, only the Agent mode gives them the intermediate queries.
BI-native tools generate against a semantic model rather than raw tables, and inspectability depends on whether the model's definitions are visible to the reviewer. Omni states that AI-generated queries use the same governed definitions as the rest of the platform, which means a reviewer can check the query against a metric definition they can read. Power BI Copilot generates DAX, and Microsoft's own guidance tells users to review the generated DAX before applying it to the model — an explicit acknowledgment that the output requires human inspection. Looker Conversational Analytics is grounded in the Looker semantic model, so the query inherits the model's structure and can be traced back through it.
Code-notebook tools make inspectability their positioning. Hex describes its Notebook Agent as intended for technical users "who can audit the SQL and code that the agent suggests" — the audit is the product, not an afterthought.
Open-source frameworks expose the pipeline by construction. Wren AI's service component handles retrieval, prompting, SQL generation, and validation as separate stages, and Vanna's architecture separates generation from validation. You can see each step because you assembled them.
The practical consequence: a tool that hides the query behind a proprietary layer cannot pass the acceptance checklist later in this article. You cannot test whether a metric definition was respected if you cannot see the query that computed it. Treat inspectability as a gate, not a score.
Permission Enforcement: Native, Inherited, or Absent?
Permission enforcement comes in three shapes, and the shape determines who is accountable when access goes wrong.
Native enforcement means the platform applies its own governance model to every AI query. Snowflake's semantic views are the recommended approach for Cortex Analyst precisely because they carry full RBAC, privilege management, and governance features, and access to a semantic model YAML uploaded to a stage is controlled by that stage's privileges. Databricks Genie Agents inherit permissions from their enclosing workspace folder like other workspace objects, and — importantly — data access is always evaluated using each end user's own Unity Catalog permissions, even though the agent embeds the author's compute credentials for warehouse access. That separation is the right design: the agent can reach the warehouse, but it cannot reach data the asking user could not.
Inherited enforcement means the AI layer defers to a governance model that already exists. Omni states that every AI query respects row-level security and user-level access controls, so users only see data they are authorized to access. Looker Conversational Analytics is grounded in the Looker semantic model, which carries Looker's governance; data agents require access_data and other permissions on the underlying models, and sharing an agent does not grant access to the Explores behind it. Power BI Copilot operates within the tenant, and tenant administrators can enable or disable it through the admin portal.
Deployer responsibility is the open-source position. Vanna's security FAQ frames data handling as a deployment-configuration question: in self-hosted mode with local storage, data stays on your infrastructure unless you explicitly configure an integration, and the vendor states that self-hosted deployments carry full control and responsibility for compliance. Wren AI OSS lists access control as part of its collaboration layer, which is accurate — it is a capability you configure, not a governance model you inherit.
The evaluation trap is the same one that corrupts benchmark readings. A demo or benchmark run as a superuser tells you nothing about governed access. Every permission test in your pilot must run as a non-superuser persona with a known row-level and column-level scope, and you must confirm that the agent's answer changes when the persona changes.
Semantic Modeling Burden: What Must the Team Build First?
This is where the article's thesis lives. Every tool on the list requires modeling; they differ in what you build and who owns it.
Execution accuracy on the same o1-preview code-agent framework across three benchmarks, as reported in the Spider 2.0 paper and summarized by Colrows. The model is held constant; only the schema changes — Spider 1.0's small, clean academic schemas, BIRD's larger and dirtier databases, and Spider 2.0's 632 real enterprise workflows with schemas averaging roughly 800 columns. These are benchmark results, not measurements of any vendor product on your warehouse.
Cortex Analyst needs a semantic view — a YAML definition with dimensions that provide categorical context and facts that capture row-level quantitative data. ThoughtSpot Spotter is built on the BI industry's relational search model and requires data-model readiness before deployment, plus ongoing coaching so it understands your business's unique terms and rules. Omni requires its semantic model and offers a Modeling Agent that drafts measures and topics while you edit YAML, alongside Evals for measuring accuracy. Hex offers semantic models with a Modeling Agent, and its Threads agent prioritizes endorsed and semantically modeled data. Wren AI uses MDL to describe relationships, calculations, and business-friendly abstractions. Vanna is a framework where you supply the training context yourself.
The evidence that modeling is the lever is consistent in direction, though you should read every number at its actual scope. A dbt Labs benchmark published 7 April 2026 reports GPT-5.3 Codex moving from 84.1% raw to 100% through the dbt Semantic Layer on an 11-question ACME Insurance set with 15 tables; Claude Sonnet 4.6 moved from 90.0% to 98.2% on the same set. That is a small, vendor-run benchmark, not an independent enterprise result. Separately, a Snowflake-internal 150-question set lifted a curated semantic model to 90%+ against 51% for the same class of single-shot LLM — also vendor-internal, also not transferable.
The direction is the finding: in both cases, adding a curated semantic layer moved accuracy by tens of points without changing the underlying model class. The absolute figures are not. An 11-question set cannot represent your schema, and a vendor's internal question set is not your workload. What you can take to a pilot is the hypothesis — that modeling hours buy more accuracy than model choice — and a way to test it: measure the modeling hours required before the first trustworthy answer, and compare that against the accuracy you get without the model.
Metric-Definition Inheritance: Testing Whether the Tool Respects Your Definitions
The acceptance test for metric inheritance is simple to describe and revealing to run. Pick three metrics your organization genuinely defines more than one way — "active customer," "net revenue," and "churned account" are reliable choices — and ask each candidate tool to compute them. Record which of three behaviors you observe: the tool returns the governed definition, the tool silently picks one definition, or the tool surfaces the ambiguity and asks.
dbt Labs' own evaluation, published 7 April 2026: 11 questions on an ACME Insurance schema of 15 tables, 20 runs per condition, comparing each model raw against the same model behind the dbt Semantic Layer. This is a small, vendor-run benchmark, not an independent enterprise result — the direction (a curated semantic layer moves accuracy by tens of points) is the transferable finding; the absolute figures are not.
Only the third behavior is safe in a regulated setting, and only the first is efficient at scale. A tool that silently picks one definition is worse than a tool that fails, because it produces a confident number that looks like every other number in the dashboard.
Several vendors ship features that support this test directly. Omni's Evals let you create prompt sets, run them against a model branch with a built-in accuracy judge, and compare runs side by side; its Suggestions feature turns real AI sessions and user feedback into a prioritized, reviewable list of model improvements. Snowflake's Cortex Analyst evaluations test semantic views against their own verified queries as ground truth, and the Evaluations tab lets you inspect a completed run by reviewing the expected versus generated SQL for each query. Hex's Context Studio lets admins monitor AI usage and review agent reasoning, then adjust workspace rules, semantic models, and endorsements.
One warning applies to every ground-truth mechanism. Snowflake's own documentation notes that if verified queries reference time-relative concepts — "last quarter" rather than "Q1 2025" — evaluation results may drift over time, and recommends scoping queries to specific, absolute dates. Build your test set with absolute dates and fixed time ranges, or you will be measuring the calendar rather than the tool.
Open-Source Frameworks vs Commercial Tools: The Real Trade-Offs
The honest comparison is total cost of ownership, not license price.
Open-source frameworks give you deployment control, self-hosting, and no per-seat ceiling. Wren AI OSS is an open-source GenBI agent with a UI, a service layer for retrieval and SQL generation, and a core modeling layer, installable on your own infrastructure. Vanna is deployment-agnostic, and in self-hosted mode with local storage, data stays on your infrastructure with no transmission to vendor servers unless you configure an integration. What you own in exchange: model maintenance, permission enforcement, evaluation harnesses, and upgrades. Vanna's own documentation is direct about this — self-hosted deployments carry full control and responsibility for compliance.
Commercial tools bundle governance, evaluation tooling, and support, and they impose seat pricing, model-provider constraints, and vendor roadmaps. The governance details are worth reading closely because they differ. Hex states that its AI providers do not train on customer data and operate under zero data retention agreements by default, with certain advanced models requiring the provider to retain prompts and outputs for a limited period for safety monitoring — those models are only available when a workspace admin enables them, and BYOK is available on the Enterprise plan. Power BI Copilot does not store prompts or responses after a session ends, keeps data inside the tenant, does not use it to train foundation models, and can be toggled tenant-wide by administrators.
The decision reduces to a staffing question: who on your team will own the semantic model in month twelve? If the answer is a named data engineer with time allocated, open source is viable and the control is real. If the answer is nobody, a commercial tool's bundled governance is not a luxury — it is the thing that keeps the deployment from quietly rotting.
Stack Fit: Snowflake, Databricks, BigQuery, and Lakehouse-Native
Snowflake. Cortex Analyst is native, available in a documented list of regions, and can be toggled at the account level. Its semantic views carry Snowflake's RBAC and privilege model, and evaluations run against verified queries you define. The constraint to check first is regional availability — if your account is not in a supported region, the native path is closed regardless of how well the tool scores.
Databricks. Genie Agents are workspace objects with folder-inherited permissions and three modes: Chat for single-query structured questions, standard Agent mode for multi-step exploratory analysis that returns a report with citations and supporting tables, and Flash (Beta) for fast answers to simple questions. A knowledge store holds agent-scoped semantic definitions — table and column descriptions, synonyms, joins, SQL expressions — that do not affect Unity Catalog metadata, and benchmarks are evaluation-only, meaning Genie does not use benchmark questions to improve its context.
BigQuery. Google's conversational analytics data agents block DDL and DML statements: the system performs a test run on generated SQL and only permits SELECT-type queries. If advanced analysis with Python is enabled, returned Python is designed to execute within a secure, Google-managed sandbox, and Google warns that running it locally or in another unverified environment bypasses those protections. That is a real operational constraint if your team's habit is to copy generated code into a notebook.
Looker Conversational Analytics spans BigQuery, AlloyDB, Redshift, Snowflake, and Databricks through the Looker semantic model, which is the strongest argument for teams already standardized on Looker: one modeling surface, multiple engines. Note the feature boundaries — Explore conversations are limited to a single Explore and are not shareable, while data agents support up to five connected Explores and can be shared with view or edit access.
Lakehouse and multi-engine. Wren AI's context layer targets multiple engines through MDL, and Vanna is deployment-agnostic. If you run more than one engine, add a portability test to your pilot: dialect divergence means the same question compiles differently across engines, so a tool that performs well on one engine has not demonstrated that it performs well on the other.
Who Should Choose Which
Teams already standardized on a warehouse should start with the native option and accept its limits. Cortex Analyst on Snowflake or Genie Agents on Databricks inherit governance you already operate, which removes an entire category of security review. Check region and feature availability before you commit, because those are the constraints that cannot be engineered around.
Teams with a mature BI semantic layer should extend it rather than adding a second modeling surface. If your metrics already live in LookML, Omni, or a Power BI semantic model, a conversational layer grounded in that model reuses work you have done and avoids the failure mode where two tools disagree about the same metric. The cost of a second modeling surface is not the initial build; it is the drift.
Code-first analytics teams should look at notebook agents. Hex's positioning is explicit — the Notebook Agent is for technical users who can audit the SQL and code — and that is the right fit for a team that already reviews queries as part of its workflow.
Teams that need self-hosting or multi-engine portability should evaluate the open-source frameworks with clear eyes about ownership. Wren AI and Vanna give you control and no seat ceiling; they also give you the permission layer, the evaluation harness, and the upgrade path.
Where "it depends" genuinely applies: modeling capacity (who builds and maintains the semantic layer), governance maturity (whether you have a permission model worth inheriting), and whether the warehouse vendor's region and feature availability match your deployment. Those three answers narrow the list faster than any feature comparison.
Verdict
The semantic model and the permission model do the work; the LLM is the least differentiated part of the stack. That conclusion is supported in two parts: benchmark results for the same o1-preview code-agent framework range from 91.2% on Spider 1.0's small, clean academic schemas to 21.3% on Spider 2.0's 632 enterprise workflows, and the dbt Semantic Layer moved GPT-5.3 Codex from 84.1% to 100%; the permission-model part rests on the vendor documentation rather than on those figures.
The practical recommendation is a two-track shortlist. For governed speed, start with the warehouse-native option your stack already supports — Cortex Analyst on Snowflake, Genie Agents on Databricks — and accept the region and feature constraints in exchange for inherited governance. For portability and control, evaluate a BI-native layer grounded in a semantic model you already maintain, or an open-source framework if you have named ownership for the modeling and permission work.
Then run a pilot measured against the acceptance checklist below, not against vendor benchmarks. The checklist is deliberately built around the conditions benchmarks omit: governed users, conflicting definitions, absolute dates, and the modeling hours before the first trustworthy answer. A tool that passes those tests on your data has demonstrated something a benchmark score cannot.
Acceptance Checklist for a Text-to-SQL Pilot
Run every test as a governed non-superuser. Create at least two personas with different row-level and column-level scopes and confirm the agent's answers differ accordingly. A superuser run measures nothing about production access.
Verify row- and column-level enforcement per persona. Ask a question that requires a column the persona cannot see and confirm the tool blocks or redacts rather than answering.
Confirm generated SQL is visible and executable by a reviewer. If the query is hidden behind a proprietary layer, stop here — the remaining tests cannot be run.
Test three conflicting metric definitions. Use metrics your organization genuinely defines more than one way, and record whether the tool returns the governed definition, silently picks one, or surfaces the ambiguity.
Scope evaluation questions to absolute dates. Time-relative ground truth drifts; use fixed dates and ranges so results are comparable across runs.
Measure modeling hours before the first trustworthy answer. Record the hours spent on semantic definitions, descriptions, synonyms, and example queries. This number, not the license price, predicts your month-twelve cost.
Confirm data-retention and training terms in writing. Ask specifically about zero-retention defaults, any models that require limited retention, and whether your data is used for training.
Test dialect portability if you run more than one engine. Ask the same question against each engine and compare the generated SQL and the result.
FAQ
Why does Spider 2.0's 21.3% matter more than Spider 1.0's 91.2% for enterprise buyers?
Because Spider 2.0 was built to resemble production. Its 632 workflows use schemas averaging roughly 800 columns, with the ambiguous names and undocumented joins that real warehouses accumulate. Spider 1.0's small, clean, cross-domain schemas measure SQL syntax ability, which is not where enterprise deployments fail. The 70-point gap between the two, produced by the same o1-preview framework, is the clearest available evidence that benchmark scores do not transfer to enterprise schemas.
Is a semantic layer mandatory?
It is the strongest lever the available evidence identifies, but the absolute figures are not transferable. The dbt Labs benchmark (11 questions, vendor-run) and the Snowflake-internal set (150 questions, vendor-internal) both show large gains from a curated semantic layer, and neither is an independent enterprise result. Treat the direction as a hypothesis to test in your own pilot and measure the modeling hours it costs.
Can open-source tools meet enterprise governance requirements?
It depends on what the deploying team builds. Vanna's documentation frames self-hosted compliance as the deployer's responsibility, and Wren AI OSS lists access control as a collaboration-layer capability you configure. If you have named ownership for the permission layer and the evaluation harness, open source is viable. If you do not, the governance gap is real.
How should I read vendor-reported accuracy claims?
As claims to validate in your own environment. Ask what the benchmark measured, how many questions it contained, whether it ran as a superuser, and whether a semantic layer was in place. A figure that omits those conditions measures the benchmark, not the system.
The Semantic Layer Is the Product
The title's framing is the article's argument: well-aligned agents on poorly aligned teams produce confident wrong answers. The agent will write SQL. It will write it quickly, in the right dialect, and with a plausible join path. What it will not do is know that "net revenue" means something specific at your company, that the customer table has three versions, or that the person asking is not entitled to the row they just requested.
Those are team problems, and they are solved before the pilot starts — in the semantic model, the permission model, and the metric ownership that the acceptance checklist tests. Take the checklist into evaluation, run it against your data with your personas, and let the results narrow the shortlist. The tool that passes is the one your team can keep aligned after the demo ends.
Previous posts
1. https://singdata.com/trending/natural-language-analytics-tools-permission-controls/
2. https://singdata.com/trending/vector-index-row-level-security-layout