
Top 10 Data Lakehouse Platforms in 2026
A buyer's shortlist of ten data lakehouse platforms available in 2026, covering open table format support, catalog and write-access limits, governance enforcement, and cost mechanics — with a proof-of-concept checklist for validating vendor claims.
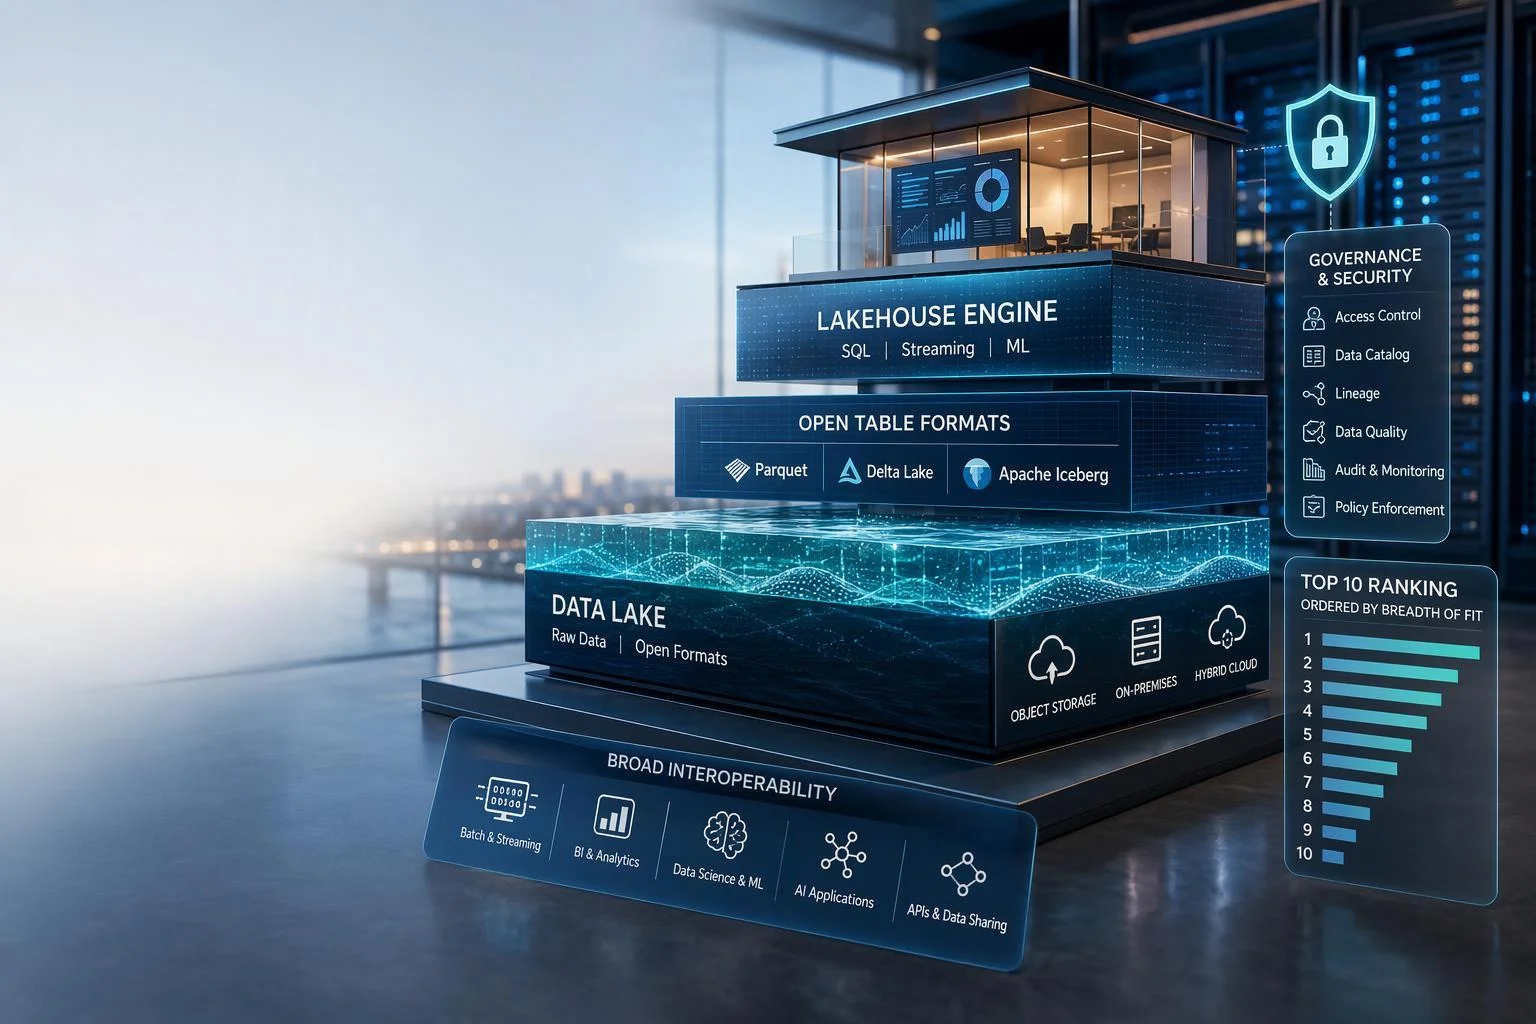
A platform qualifies for this list if a buyer can procure it in 2026 and run governed analytics over open table formats on object storage — not merely query a warehouse. Each entry below is a lakehouse in that operational sense: it stores data in Iceberg, Delta, or both, exposes a catalog that other engines can reach, and enforces access controls somewhere between the storage layer and the query.
The order reflects breadth of fit across four buyer profiles — cloud-native analytics, open-format interoperability, unified BI-plus-engineering estates, and hybrid or on-premises control — not a benchmark ranking. Vendor performance and cost figures cited here are vendor-reported claims to validate in your own environment. Treat this as a shortlist to test, not a verdict.
1. Databricks
Databricks is the reference implementation of the lakehouse pattern. Delta Lake is its storage foundation — an open-source layer that extends Parquet files with a transaction log for ACID transactions and scalable metadata handling, tightly integrated with Spark APIs and Structured Streaming. Iceberg interoperability runs through Unity Catalog's Iceberg REST endpoint, which lets external engines read and write Unity Catalog-registered Iceberg tables.
Best fit: Spark-centric engineering and ML teams already running on AWS, Azure, or GCP, where one copy of data serves batch, streaming, and model training. The trade-off is that cost governance and warehouse-style SQL concurrency need deliberate capacity planning; per-second pay-as-you-go billing rewards disciplined cluster policy rather than ad hoc sizing.
What to test: read and write behavior across table types. Databricks' own external access matrix shows write access limited to managed Iceberg tables — foreign Iceberg tables, managed Delta with Iceberg reads enabled, and external Delta are read-only through that endpoint. Foreign Iceberg tables also are not automatically refreshed and require REFRESH FOREIGN TABLE to pick up the latest snapshot. If external engines must write, confirm which table type your pipeline actually produces.
2. Snowflake
Snowflake entered lakehouse territory from the warehouse side, through Iceberg tables whose data and metadata live in cloud storage via an external volume. The platform offers two catalog modes, and they are not equivalent: with Snowflake as the catalog, Snowflake manages table maintenance and broader platform features; with an external catalog, you get catalog-vended credentials and integration with external engines, but not full Snowflake platform support.
Best fit: SQL-centric organizations that want governed analytics over open storage without abandoning an existing warehouse investment. The trade-off is billing surface area. Snowflake bills fail-safe storage on Iceberg tables, and if your account and external volume sit in different regions, your cloud storage account incurs egress costs on every query — with cross-region data transfer charges on Snowflake-managed tables as well.
What to test: which catalog mode your governance and multi-engine requirements actually demand. If other engines must write to your tables, verify that path against the external-catalog configuration rather than assuming parity with Snowflake-managed tables.
3. Google BigQuery
BigQuery pairs a serverless analytics engine with BigLake support for Iceberg tables, positioning open-format access alongside native query performance. Google's own framing of the category emphasizes convergence between the analytical lakehouse and operational databases — BigQuery, Managed Service for Apache Spark, Spanner, and AlloyDB working as one system — which matters if your agents or applications need to act on fresh operational data rather than a nightly copy.
Best fit: GCP-anchored organizations that want minimal infrastructure operations and are willing to accept Google's pricing mechanics. The trade-off is that the two pricing models behave very differently. On-demand billing charges per TiB scanned; capacity pricing charges per slot-hour, with commitments sold in 50-slot minimums and increments, and commitments are regional — capacity bought in one region cannot be used in another. The 300 TiB monthly free tier applies to the bytes-read component of the Storage Read API and does not cover associated outbound data transfer.
What to test: whether your workload profile fits slot commitments or on-demand billing. Run a representative month of queries under both models before committing, and check whether load jobs assigned to a reservation lose access to the free shared pool.
4. Microsoft Fabric
Fabric is a tenant-wide analytics platform rather than a standalone lakehouse product. OneLake is included with every Fabric tenant and stores tables in Delta Parquet or Iceberg, two open standards any tool can read. Its security model defines granular permissions on data items down to folders, tables, rows, and columns, and OneLake enforces those roles across SQL, Spark notebooks, and Power BI reports alike — a genuinely useful property if your governance problem is inconsistent enforcement across tools.
Best fit: Microsoft-centric estates that want BI, data engineering, and lakehouse workloads in one governed tenant. The trade-off is shared capacity. Each capacity is a distinct resource pool, and smoothing and bursting let you size closer to average usage than peak demand — but sustained overutilization may trigger staged throttling. Shared capacities also make it hard to attribute cost to the team that caused it, which is why Microsoft documents a chargeback app and capacity tagging as part of cost governance.
What to test: chargeback visibility and throttling behavior under your real concurrency. Note that a capacity reservation discount applies to capacity units hourly and does not carry over if workloads do not consume them for a full hour.
5. Amazon S3 Tables with AWS Glue
S3 Tables is AWS's managed Iceberg table service, with automated table optimization covering compaction, snapshot management, and related maintenance. Once a table bucket is integrated with the Glue Data Catalog, Iceberg-compatible clients such as PyIceberg or Spark connect through the AWS Glue Iceberg REST endpoint, which implements the Iceberg REST Catalog Open API specification.
Best fit: AWS-first teams that want open-format tables without operating a catalog or writing their own compaction jobs. The trade-off is that access is not automatic. Reaching S3 tables through the endpoint requires permissions configured through a combination of IAM policies and AWS Lake Formation grants, including an IAM role, the required policies, and database- and table-level Lake Formation permissions. OAuth-based access adds identity-federation setup on top.
What to test: permission models for cross-engine access. Confirm that each engine you plan to connect — not just your primary one — can authenticate and that Lake Formation grants resolve at the granularity your governance requires. Budget the governance setup as a project, not a configuration step.
6. Starburst
Starburst is a federated query layer built on open-source Trino, aimed at estates that span many sources rather than one lake. It supports Iceberg, Delta Lake, and Hudi, so the same data stays reachable by multiple engines without conversion or duplication — a meaningful difference from platforms that center on a single table format.
Best fit: organizations whose data is not in one lake and cannot practically be consolidated, including those where agents need to reason across databases, warehouses, object stores, and SaaS systems. The trade-off is that federation performance varies by source and by how much predicate and projection pushdown each connector supports; a query that pushes down cleanly to one system may pull far more data than expected from another.
What to test: your hardest cross-source query. Starburst publishes comparison figures against Dremio — a 2.5x connector gap, 30–55% price-performance advantage, and 45% lower total cost of ownership, attributed to ESG/Omdia 2026 — but these are vendor-published claims about a competitor. Starburst's own guidance is to treat vendor benchmarks as a starting point and run a proof of concept on your workloads, your concurrency, and your mix of sources.
7. Dremio
Dremio is an Iceberg-centric lakehouse whose centerpiece is a managed Open Catalog built on the open Apache Polaris project. Every engine connects through the Iceberg REST API — Dremio itself, Spark, Flink, Trino, DuckDB — and governance plus table maintenance are managed once at the catalog layer rather than repeated per engine.
The governance model is worth understanding in detail because it is the product's main argument. Dremio describes four layers of control: storage-level through credential vending with temporary, scoped credentials per query; table-level through role-based access control privilege grants; external-source access through impersonated access; and column- and row-level through masking and row-access policies.
Best fit: teams standardizing on Iceberg that want a universal catalog governing many connected engines. The trade-off is narrower connector breadth than federation-first platforms — Dremio's connectors focus on lakehouse and object-store sources, so an estate with many operational systems may need a different access layer. What to test: governance enforcement across every engine you actually connect, including whether row filters and column masks hold when a query arrives through a third-party client rather than Dremio's own engine.
8. Cloudera Open Data Lakehouse
Cloudera positions its Open Data Lakehouse as a hybrid deployment — cloud or on-premises — and documents interoperability with external engines through the Iceberg REST Catalog. That combination is the reason it belongs on this list: most of the platforms above assume you will run in their cloud, and Cloudera does not.
Best fit: regulated or sovereignty-sensitive organizations, and enterprises with substantial existing Hadoop or on-premises investment that cannot be written off. Where data residency rules or internal policy require data to stay in a specific facility, a hybrid lakehouse with REST Catalog interoperability preserves the open-format benefit that a fully managed cloud service would otherwise force you to trade away.
The trade-off is operational burden relative to fully managed services. You carry more of the platform engineering: upgrades, capacity planning, and the maintenance jobs that managed services automate. What to test: which engines you need through the REST catalog and how they behave against your storage — particularly write paths and metadata refresh behavior, since catalog interoperability claims often hold for reads more readily than for writes.
9. IBM watsonx.data
IBM watsonx.data is a hybrid lakehouse offered as a subscription, as a fully managed multi-cloud service on IBM Cloud and AWS, and as an on-premises software offering. It uses a fit-for-purpose, multi-engine architecture: each workload runs on the engine best suited to it, with governance built into the platform rather than added per engine.
Best fit: IBM-anchored enterprises that want a governed lakehouse with adjacent AI tooling and the option to keep data in their own VPC. The on-premises and bring-your-own-cloud options are the differentiator — IBM explicitly frames the software-only purchase as a way to use existing infrastructure and cloud credits while retaining control over data residency and security.
The trade-off is pricing structure. watsonx.data is priced starting at $1.00 USD per resource unit, which means your bill depends on how your workload shape maps onto resource-unit consumption — a figure that is difficult to forecast from list price alone. What to test: resource-unit consumption under representative queries, including your heaviest concurrent analytical workload, and model the monthly total against your actual query mix rather than a single benchmark run.
10. Singdata Lakehouse
Singdata is a cloud-agnostic, AI-native lakehouse built on Apache Iceberg, offered as a managed SaaS across multiple global clouds and CPU architectures. Its architecture collapses what are usually separate layers — Spark for batch, Flink for streaming, and a warehouse for SQL — into a single engine, with incremental compute as the mechanism for processing only what changed rather than recomputing whole datasets.
Best fit: teams that want to reduce the number of systems they operate while keeping governed access and putting AI agents on top of the same data. The SPOT standard Singdata describes — Standard SQL, Performance optimization, Open Format compatibility, and Trade-offs — is a useful frame for evaluating it, because it maps to questions you can test rather than headline numbers.
The trade-off is maturity: Singdata is a younger platform than the vendors above, so ecosystem breadth, third-party integrations, and the hiring pool of engineers who already know it should be weighed honestly against the architectural simplification. What to test: your incremental and real-time workloads against the unified engine. Singdata's published performance claims are vendor claims — validate them against your own data volumes and concurrency before treating them as a planning input. If you are comparing against an incumbent, this evaluation framework for Databricks and Snowflake alternatives sets out the criteria in a form you can run as a scorecard.
How to Test Vendor Claims Before You Commit
Every platform above publishes performance and cost figures. None of them are measured on your data, your concurrency, or your query mix, so the only reliable method is to reproduce the comparison in your own environment.
Start by defining representative workloads rather than a single benchmark query. Pick three to five jobs that cover your actual pattern: a high-concurrency BI burst, a large batch transformation, an incremental or streaming pipeline, and — if it applies — a cross-source join. Record data volumes, concurrency, and freshness requirements for each. Then run them on the candidate platform with your data, not a vendor sample dataset, and measure wall-clock time and cost per workload rather than list price per unit.
Cost is where vendor claims diverge most from invoices, because headline rates exclude the mechanics that actually bill. Four documented examples show the pattern. Snowflake bills fail-safe storage on Iceberg tables and incurs egress when your account and external volume sit in different regions. BigQuery's 300 TiB bytes-read free tier covers only the read component and excludes outbound data transfer, and slot commitments are regional. Fabric's smoothing and bursting let you size to average usage, but sustained overutilization triggers staged throttling — and a capacity reservation discount does not carry over if capacity units go unused for a full hour. IBM prices watsonx.data per resource unit, so the bill follows workload shape rather than a fixed rate.
A practical sequence: run the proof of concept for at least two weeks to capture a full reporting cycle; instrument cost per workload, not just total spend; test at your peak concurrency rather than average; and write down the assumptions each vendor used in its own benchmark so you can see which ones your environment violates. If a vendor will not run your workload on your data, that is itself a data point.
Open Formats, Lock-In, and Governance Risk
Open table formats reduce lock-in only to the extent that you can both read and write the data from engines outside the platform that created it. That distinction is where most evaluations go wrong.
Consider the documented write restrictions. Databricks' external access matrix grants external Iceberg clients read and write on managed Iceberg tables, but read only on foreign Iceberg tables and on Delta tables with Iceberg reads enabled. Snowflake's Iceberg table documentation shows read and write in both catalog modes, with catalog-vended credentials available only in the external-catalog mode. The lesson is that "supports Iceberg" is not a portability guarantee; the question is which engines can write, through which catalog, under which table type.
Catalog choice is the control point. A Snowflake-managed table and an externally cataloged table carry different capability sets. A Unity Catalog table and a table registered in an external REST catalog behave differently for external writers. If portability is a requirement, the catalog — not the file format — is what you are actually choosing, and it should be evaluated as such.
Governance enforcement deserves the same specificity. Verify controls at four levels: storage (credential vending and scoped access), table (privilege grants), row (row-access policies), and column (masking). Then test whether each level holds when the query arrives from a connected engine rather than the platform's native one. Databricks documents that reading tables with row filters or column masks from an external Iceberg client requires specific client versions and configuration — a reminder that cross-engine governance is a configuration property, not an automatic one. Dremio's Open Catalog makes a similar claim across connected engines; test it with a third-party client. For a deeper treatment of enforcing row-level and role-based controls in practice, see this governance implementation guide.
Acceptance Checklist for Procurement
Use this list as the agenda for a proof of concept, not as a scoring sheet to fill in from vendor collateral. Each item should produce a document you can hand to procurement: a test you ran, a result you observed, and a named owner on the vendor side who confirmed the configuration. Where a vendor cannot demonstrate an item in your environment, record that as an open risk rather than a pass.
Workload fit. Run your three most representative workloads — one high-concurrency BI pattern, one large batch transformation, and one incremental or streaming pipeline — and record latency, throughput, and failure behavior for each.
Open-format read and write. Confirm which engines can write, not just read, to your tables, and under which catalog. Databricks, for example, documents write access through its Iceberg REST endpoint for managed Iceberg tables but not for foreign Iceberg tables.
Catalog portability. Establish what happens to table metadata if you stop using the vendor's catalog, and whether an external engine can discover and query the same tables without a migration project.
Governance enforcement points. Verify that row filters, column masks, and role grants apply identically whether a user queries through SQL, a notebook, or a BI tool — and test them from an external engine, not only the native one.
Cost model transparency. Ask for a worked cost estimate against your measured workload, with the billing units named, rather than a per-unit list price.
Egress and storage billing. Identify every charge that scales with data movement or retained snapshots, including cross-region transfer and fail-safe storage, and model them at your actual volumes.
Concurrency under load. Test at or above your projected peak, not at average, and observe whether the platform throttles, queues, or degrades.
Migration path. Confirm the effort to move existing tables in, and the effort to move them out again.
Support terms. Get response targets, escalation paths, and named engineering contacts in writing before signature.
FAQ
Does a lakehouse replace our data warehouse?
Not necessarily, and not immediately. A lakehouse can absorb much of the SQL analytics workload a warehouse handles, and Microsoft documents that Fabric's lakehouse and warehouse share the same SQL engine and store data in Delta format on OneLake, differing mainly in development tools and workload patterns. But replacing a warehouse is a migration decision about concurrency, governance, and existing reporting commitments — evaluate it as a migration, not as a license swap.
Should we standardize on Iceberg or Delta Lake?
The practical answer is to check which format your chosen platform can both read and write, and which other engines you need to reach the same tables. Delta Lake is an open-source storage layer that adds a transaction log over Parquet files, and Databricks supports reading Delta tables through Iceberg-compatible interfaces. Iceberg has broad multi-vendor support. The decision hinges less on format features than on catalog choice, which determines who can write.
Can we trust vendor performance claims?
Treat them as hypotheses. Vendor-published comparisons are useful for identifying which dimensions a vendor considers important, but they are produced by parties with a commercial interest in the outcome. Reproduce the measurement in your environment with your data mix and concurrency before you let a number influence a purchasing decision.
What should a proof of concept include?
At minimum: your real data at realistic volume, your peak concurrency, at least one external engine reading and writing through the catalog, governance rules tested from that external engine, and a cost measurement per workload rather than per query.
How do open formats actually reduce lock-in?
They reduce it at the storage layer and leave the harder dependency at the catalog and compute layer. Data in open table format remains readable by other engines, but the catalog controls discovery, credentials, and write permissions. Portability is therefore a property of the whole stack, not of the file format alone.
Conclusion
There is no universal first place on this list. The platform that fits your organization depends on three things: the shape of your workloads, where your data and compute must physically sit, and how much governance you need to enforce across more than one engine. A Spark-heavy ML team and a SQL-centric finance analytics group will read the same ten entries and reach different conclusions, and both can be right.
What does carry across every option is the method. Define representative workloads before you talk to vendors. Test read and write access through the catalog, not just the query path. Measure cost per workload rather than per unit. And treat every published performance figure — including those from Singdata — as a claim to reproduce in your own environment.
The acceptance checklist above is the next step: turn it into a proof-of-concept plan, assign an owner to each item, and require evidence rather than assurances before you commit.
Previous posts
https://www.singdata.com/company
https://singdata.com/trending/powerbi-date-difference-dax-calculations/