

TRACE
See the full story
Follow the prompt, context, model, and tool calls behind every run—and find exactly where things went off track.
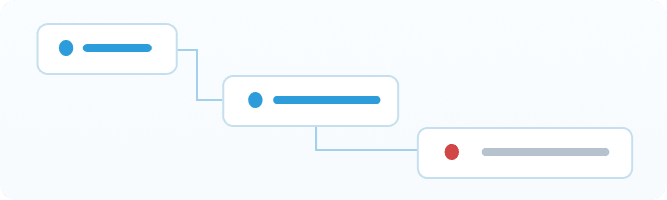

Follow every model and tool call, measure real-world task success, and optimize quality, latency, and spend.

Everything ran. The outcome was wrong.

Customer asked
Return the wristwatch
 Understood

Agent did
Returned hiking boots
Call succeeded

Actual outcome
Wrong item returned
 Task failed
No errors doesn’t mean no failure.
Follow the prompt, context, model, and tool calls behind every run—and find exactly where things went off track.

Score agents against real task outcomes, then surface the same failure pattern across production traffic.

Analyze quality, latency, and token spend in the Singdata Lakehouse, and see whether each release made a difference.
Get the full product overview, including the architecture, workflow, and a step-by-step production example.

